Key Takeaways
- Claude Opus 5.5 leads Finance Agent v2.1 with 67.85% accuracy. Gemini 4 Argon follows at 67.66%, with Wonder Full at 67.58%.
Background
Finance Agent v2.1 is a revision of Finance Agent v2, which built on Finance Agent v1.1, with question and rubric fixes from expert reviews. Dataset design, splits, and access are covered in Methodology.
What changed in v2.1: a new judge jury, a grading prompt updated for hedged answers, and data fixes to questions and rubrics. See Changes from v2.
The benchmark tests a model’s ability to perform the work of entry-level financial analysts — answering difficult questions on public company filings.
Automating analyst-grade financial research is valuable because the work is expensive, repetitive, and time-sensitive: analysts often need to move from filings and transcripts to a defensible model or investment memo under deadline. The work is also difficult because the answer depends on finding the right source, applying the right finance convention, and carrying precise intermediate numbers through several steps.
Finance Agent v2.1 measures how well AI can aid analysts in automating busy work so they can focus on higher-leverage tasks.
Results
The mid-tier models sit only a few points below the leaders at a fraction of the cost, suggesting the accuracy premium at the frontier is modest relative to the price gap.
Where Models Stand
When measuring models on their ability to perfectly answer questions, scores fall substantially across the leaderboard compared with allowing partially complete responses.
The tool call analysis reveals how many steps the models take to produce an answer. Interestingly, the top performers also register relatively high numbers of tool calls. This suggests that their comparatively strong performance is partly due to leveraging the tools provided.
The radar graph shows the per-model breakdown of tool calls across the six tools.
Model Output Examples
Did NYSE: CNC have to pay a rebate to policyholders in fiscal year 2025 or fiscal year 2020? If not, was the company closer to owing customers a rebate in 2025 or 2020? What were the medical loss ratios in each year?
100
All checks passed.
The question above is a General Quantitative Analysis task: deciding whether Centene owed a rebate to policyholders in either fiscal year based on the medical loss ratio threshold, and reporting the underlying MLRs.
Methodology
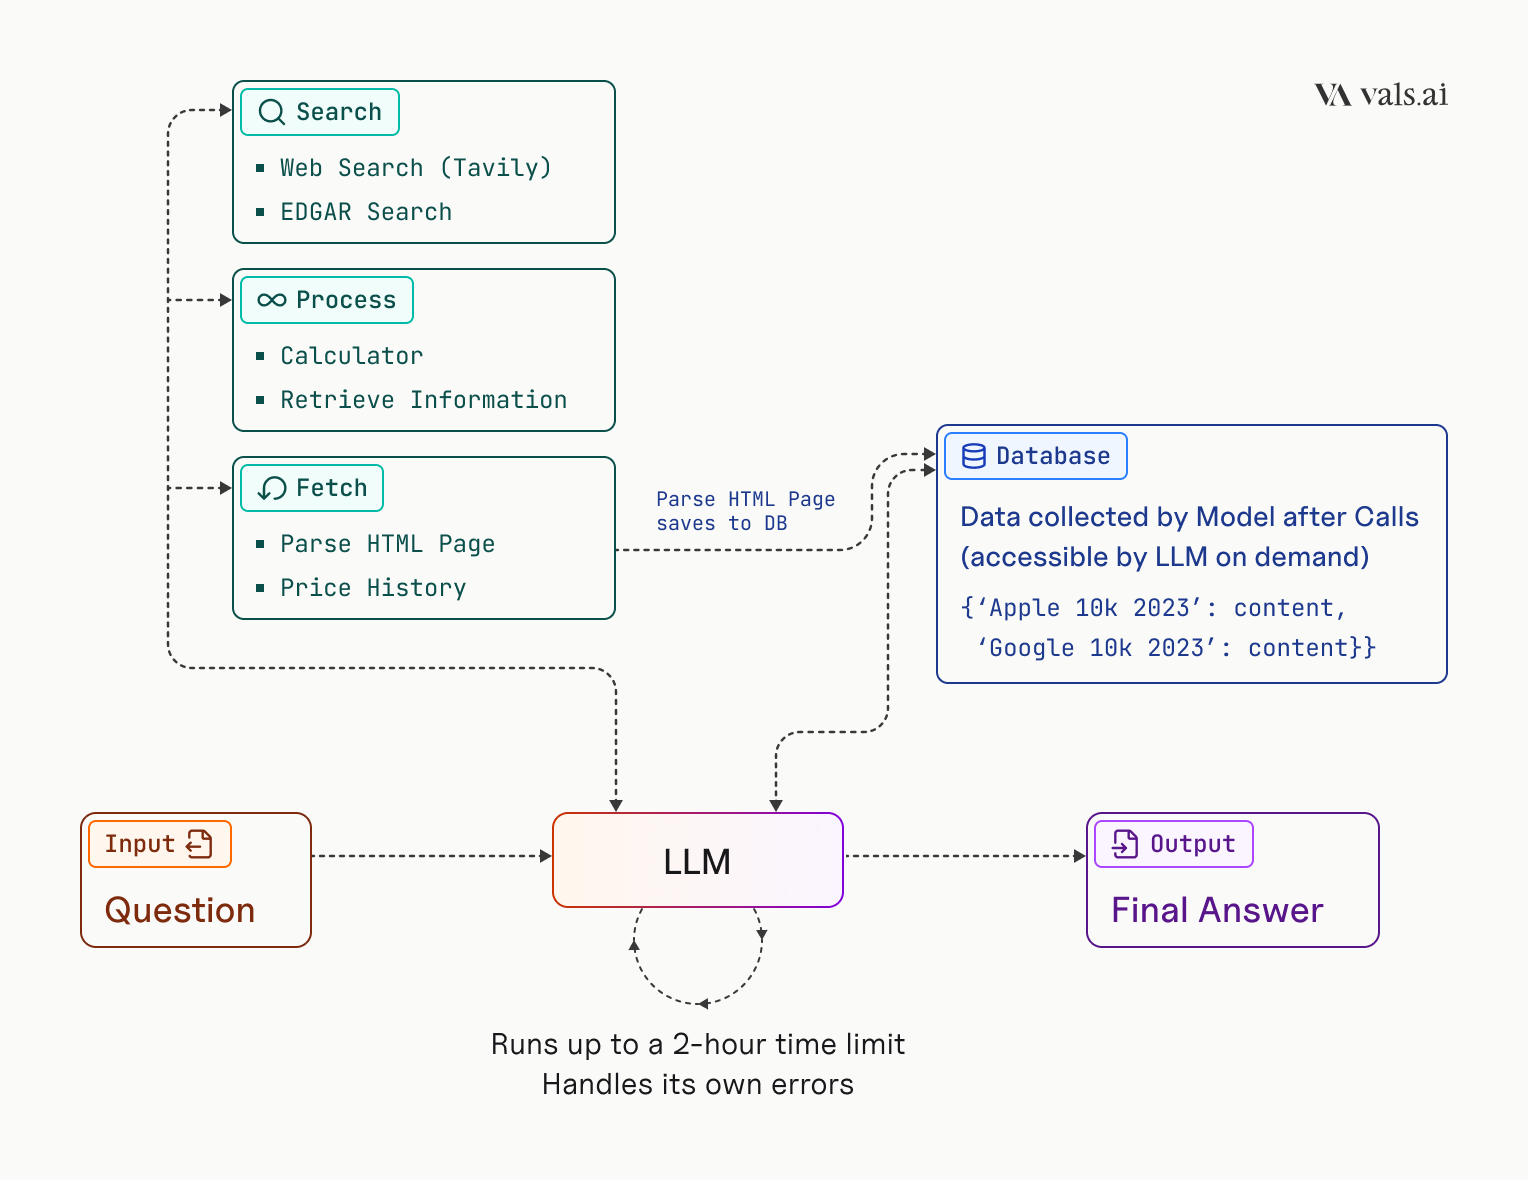
Agents are all evaluated on a shared default harness with access to six tools: edgar_search (SEC EDGAR API), web_search, parse_html_page (download an HTML page), retrieve_information (query over fetched HTML), calculator, and price_history.
Time Limit
Each task has a two-hour time limit. An answer must be produced within the time limit, otherwise the task is scored as a zero. The time limit was chosen empirically by measuring how long current frontier models need to converge on these tasks and setting the limit comfortably above that ceiling. A fixed time budget also allows us to normalize and compare performance across different agent implementations.
Grading
Each question is composed of weighted checks, and a subset are flagged as dealbreakers, load-bearing facts or numbers, that are required for a satisfactory answer. Failing any dealbreaker means the answer receives no credit for that question, regardless of the remaining content in the response. Two metrics are reported:
- Partial Credit (primary): the dealbreaker-gated, severity-weighted average of per-check scores. A response with a correct dealbreaker but a few peripheral misses scores below 100%; a response with any failed dealbreaker scores 0%.
- All-Pass (secondary): 100% only if every check passes, 0% otherwise.
All responses are graded by a three-judge LLM jury consisting of three frontier models: GPT-6.1 Sol, Gemini 3.8 Flash, and Claude Sonnet 5.5.
Changes from v2
- Question and rubric fixes. Following expert reviews, some test questions were reworded or removed and some grading checks were revised.
- New jury. GPT-6.1 Sol, Gemini 3.8 Flash, and Claude Sonnet 5.5 replace the v2 jury.
- Hedging. An answer is hedged when it gives two or more candidate values for an item without committing to one. The judge prompt now fails hedged answers, and the agent prompt now asks for one conclusive answer per item.
- Scores are not comparable with Finance Agent v2.
Changes from v1.1
- Step up in difficulty. Questions require connecting data across multiple documents, tighter numeric precision, and answers are expected to include insights that skilled analysts would include but are not explicitly stated in the question.
- Expanded taxonomy. The taxonomy was reorganized around real analyst workflows rather than retrieval tiers. v1.1’s easier retrieval-focused buckets (Quantitative Retrieval, Qualitative Retrieval, Numerical Reasoning, Complex Retrieval, Beat or Miss, Trends) are replaced with Comparables, Precedents, Earnings Analysis, Disclosure Analysis, and a split between General Qualitative and General Quantitative analysis.
- New grading mechanism. Dealbreaker-gated Partial Credit replaces v1.1’s flat per-question score, and All-Pass is reported alongside it as a strict secondary metric.
- Stricter numeric tolerances. Tighter thresholds on rounding and precision drift. Answers that previously passed under v1.1’s looser tolerance now fail.
- Expanded harness. Adds
calculatorandprice_historyon top of the v1.1 tools. - Expanded test set. Larger held-out test split for tighter measurement.
Question Design
Questions target the analytical depth expected of a 2nd or 3rd-year investment banking analyst. Each question was designed to satisfy four criteria:
- Determinism. A single, unambiguous correct answer with no room for competing interpretations.
- Multi-source synthesis. Answers require chaining information across multiple filings or data sources rather than a single lookup.
- Domain specificity. Questions require implicit industry knowledge that follows sector convention rather than explicit instruction.
- Forensic precision. Critical information is frequently buried in footnotes, MD&A caveats, or accounting policy disclosures.
Dataset
The dataset is divided into three parts: Public (27 open-source samples), Private Validation (450 samples available for license), and Test (449 samples).
- The Public set and agent harness are fully open in the Finance Agent v2 GitHub repository.
- The Private Validation set is available for license. Interested parties are encouraged to contact us directly for access.
- The Test set will remain private. All results reported on this page are based solely on the Test set to prevent overfitting.
The dataset splits were sampled to preserve the distribution of question categories and difficulty.
Question Taxonomy
Finance Agent v2 organizes questions into nine analytical categories reflecting real equity-research workflows.
General Qualitative Analysis
Summarization and comparison of fundamental filing sections: business model, risk factors, MD&A, and standard disclosures across companies.
Compare Walmart, Costco, and Target’s capital allocation priorities across capex, dividends, share repurchases, and debt management.
General Quantitative Analysis
Extraction and calculation of reported financials such as revenue growth, CAGR, leverage ratios, and executive compensation — often requiring verification against restated historicals.
Compare Home Depot and Lowe’s FY2024 inventory efficiency and calculate the difference in days inventory outstanding.
Market Analysis
Relative trading performance, total shareholder return, and how news cycles or guidance shifts drive stock volatility relative to sector indices.
Measure Sun Communities’ stock reaction after the announced sale of Safe Harbor Marinas, then relate the move to the company’s stated use of proceeds.
Comparables
Building trading comps tables, calculating EV multiples, and normalizing enterprise value across peers by adjusting for off-balance-sheet items buried in footnotes.
Rank major U.S. banks by excess CET1 ratio relative to their regulatory minimums.
Precedents
Analyzing M&A transaction multiples from S-4 filings and target financials, with industry-specific EBITDA normalization (e.g. exploration expense add-backs in Oil & Gas).
Extract enterprise values and EV/EBITDA multiples for recent industrial distribution acquisitions and rank the transactions by pre-synergy multiple.
Adjustments
Bridging GAAP to non-GAAP or pro forma figures by reconciling SBC, acquired intangible amortization, and other non-cash items across the P&L and cash flow statement.
Reconcile Honeywell’s GAAP operating income to segment profit across annual releases and identify newly introduced adjustment categories.
Earnings Analysis
Comparing reported results against consensus estimates and prior guidance, including non-GAAP reconciliations across consecutive quarterly reporting cycles.
Compare Rapid7’s Q3 2025 actuals against prior revenue, non-GAAP operating income, and ARR guidance.
Disclosure Analysis
Tracking shifts in MD&A language, KPI definitions, and segment reporting methodology across multiple annual filings, then restating prior periods to reflect the new format.
Track Boeing’s segment reporting and 787 cost-recovery disclosures across FY2022-FY2024 10-K filings.
Financial Modeling
Multi-step frameworks including DCF/NPV, LBO, and M&A accretion/dilution models built from historical ratios extracted from primary filings.
Assess whether Ralph Lauren could justify a distressed acquisition of Capri under stated synergy, margin, and valuation assumptions.
Acknowledgements
We would like to thank Andrew Schettino and all of the financial experts who worked on Finance Agent v2.
Citation
If you use this benchmark in your research, please cite the paper.
Citation (BibTeX)
@misc{bigeard2025fab,
title        = {Finance Agent Benchmark: Benchmarking LLMs on Real-world Financial Research Tasks},
author       = {Bigeard, Antoine and Nashold, Langston and Krishnan, Rayan and Wu, Shirley},
year         = {2025},
month        = may,
howpublished = {Vals AI},
url          = {https://arxiv.org/abs/2508.00828},
}