Independent Evaluation, Unbiased Benchmarks
Testing AI on Real-World Tasks
We benchmark the world's leading AI models on economically valuable tasks such as finance, software, and frontier risk like cybersecurity, recursive self improvement and mental health. We run all of our own evaluations and create many of our benchmarks in-house.
 •Oct 07, 2026
 Gemini 4 Argon67.04%
 Claude Sonnet 5.563.13%
 GPT-6 Astra58.16%
 Muse Spark 1.3 Max55.20%
 MiMo V2.6 Pro54.95%
 Grok 4.753.51%
 GLM 5.351.32%
 DeepSeek V4.1 Flash50.81%
 Ember-150.30%
 Kimi K349.94%
 Hy4 Preview49.35%
 Step 5 Preview48.27%
 Qwen 3.8 Max48.05%
 Mistral Large 436.53%
 MiniMax-M328.67%
 Inkling8.86%
 Mercury 2.5
Latest Reports
Recent benchmark releases and model evaluations.
We’ve released SAFE-Teen, a benchmark that tests how AI chatbots respond when a teen turns to them for mental-health support. We tested 10 models across 11 configurations using 101 clinician-written scenarios with simulated teens aged 13-17, each with and without a teen-aware system prompt, and rated every conversation on clinician-defined safety checks.
-
Chatbots don’t do enough to keep teens safe. Without a teen-aware prompt, failure rates on urgent safety checks range from 3% to 34% across configurations.
-
They step into a clinician’s role and encourage emotional attachment. Health-advice failure rates range from 4% to 59%, and relationship-boundary failure rates from 10% to 50% across configurations.
-
They fail more often when a teen resists. 26% of ratings after a teen declines outside help are failures, against 18% when the teen agrees.
Explore the results by model and risk area, the methodology and example conversations on SAFE-Teen.
We evaluated Anthropic’s new Claude Haiku 5.5 across our benchmark suite.
-
Haiku 5.5 places #16 of 45 on the Vals Index (54.31%) at $2.99 per test, 0.51 points behind Gemini 3.8 Flash (54.83%).
-
It takes #3 of 110 on Vibe Code Bench (90.44%), behind only Gemini 4 Argon (91.91%) and Claude Sonnet 5.5 (92.39%), and #5 of 45 on CyberBench (75.48%), ahead of Sonnet 5.5 (59.58%).
-
Further top-ten finishes on MedScribe (89.54%, #6 of 108), Vibe Code Bench 1-100 (20.41%, #7 of 22) and MysteryMechanism (35.14%, #10 of 25).
-
Compared to Claude Haiku 4.5 (Thinking), it improves from 11.39% to 90.44% on Vibe Code Bench, 7.55% to 44.57% on Code Migration, 22.66% to 59.02% on EMB and 10.58% to 43.27% on Legal Research Bench.
-
Weaker on SRE Bench (5.73%, #15 of 33), Terminal-Bench Science (10.00%), SAGE (45.78%, #38 of 91) and Harvey’s Legal Agent Benchmark (1.25%).
We ran Haiku 5.5 without a refusal fallback. Content-filter refusals are scored as failures, including 8 of 270 BioMysteryBench attempts and 1 of 70 Terminal-Bench Science tasks.
Haiku 5.5 is priced at $0.10 per million input tokens and $0.50 per million output tokens. The model has a 1M-token context window and 128k max output tokens. Evaluations were run with compute effort set to “max”.
Congrats to the Anthropic team on the release!
Jev, a TypeSafe model, does not generate text. You give it a state and questions with allowed answers, and it returns a probability distribution over the options for each one. Input costs $0.042 per million tokens and output is free, so our written-answer benchmarks cannot score it.
We built two that can: 400 claim-verification items made from SEC filings, and a preregistered 12-subtask slice of LegalBench. Across twelve systems, Jev scores 0.975 on claim verification at $0.02 per 1,000 cases, tying GPT-6 Astra, GPT-6.1 Sol and GPT-6 Luna at about 1/500th of GPT-6 Astra’s cost, and answers in about a tenth of a second. On LegalBench it finishes last of twelve.
We asked Claude Opus 5.5 agents to find a room-temperature magnet with zero net magnetism whose electrons are still sorted by spin, a combination physicists call a Luttinger-compensated magnet. Their own design, YBaMnFeO₅, looks ideal on paper, but their follow-up calculations suggest it may be hard to make.
They then found that KV[Cr(CN)₆], a magnet first made in 1999 whose sample stayed magnetic up to 376 K, fits the description in their calculations. The inputs, raw outputs and analysis code behind the post’s numbers are in a ledger linked from the post.
Web search hasn’t been measured well, and we weren’t the only ones to notice. Search providers have built their own benchmarks to work around data contamination, unrealistic tasks, and answers leaking onto the web. When a benchmark measures the wrong thing, customers can’t tell which search tool is best for their work. We think the teams building these tools deserve a third-party benchmark that measures the work their users actually need done.
We’re excited to share that Exa, Keenable, Parallel, and Tavily are joining us as partners on the Vals Web Search Index: one benchmark, the same settings for every provider, run independently.
In the blog post, we go over why BrowseComp rewards memorized knowledge and leaked answers more than search, then how search providers have tackled the problem with their own benchmarks, and finally how the Web Search Index scores an agent’s final answer on expert-written legal and finance tasks from a private test set, swapping only the search tool while the model and harness stay fixed.
We evaluated specialized AI detectors and language models on 494 private writing samples: 247 human-authored documents and 247 AI rewrites. The rewrites use prompts designed to retain the authors’ voices, then pass a check that more than half the original word sequence changed.
Claude Opus 5.5 leads the balanced-accuracy leaderboard at 98.38%, followed by GPT-6 Astra at 95.75%. A separate stress test asks frontier models to rewrite validation passages and measures whether they can identify those rewrites themselves.
We evaluated Google’s new Gemini 4 Argon across our benchmark suite.
-
Gemini 4 Argon places #1 of 41 on the Vals Index (68.90%) at $15.68 per test, ahead of Claude Sonnet 5.5 (67.04%, $21.34 per test), Claude Opus 5.5 (66.97%, $32.14) and Claude Fable 5.1 (65.83%, $28.71).
-
It takes #1 on Finance Agent v2 (65.40% of 73, ahead of Gemini 3.8 Flash at 61.44%) and ties GPT-6 Astra for #1 on IOI with a perfect 100.00%.
-
It sits at #2 on Vibe Code Bench (91.91% of 106, behind Sonnet 5.5 at 92.39%), Code Migration (68.17% of 71, behind Sonnet 5.5 at 69.83%) and CyberBench (77.86% of 43, 0.12 points behind GPT-6 Sol), and at #3 on LegalBench (88.30% of 149), MedCode (58.80% of 104), Terminal-Bench Science (44.29% of 34) and SRE Bench (44.28% of 16).
-
Further top-ten finishes on Tax Agent Bench (44.56%, #4 of 64), Legal Research Bench (54.81%, #4 of 72), EMB (75.24%, #4 of 69), the Vals RSI Index (30.55%, #4 of 23), Terminal-Bench 4.0 (57.58%, #5 of 42), Harvey’s Legal Agent Benchmark (19.58%, #5 of 73), SAGE (53.65%, #5 of 90), Public Benefits Bench (69.76%, #5 of 45), ProgramBench (2.50% fully resolved, #5 of 54), ProofBench v1.1 (99.00%, #5 of 46, one point behind a four-way tie at 100.00%), BioMysteryBench (76.30%, #6 of 21) and MysteryMechanism (45.50%, #6 of 21).
-
Weaker on MedScribe (87.43%, #15 of 106) and CUA-bench (4.83%, #7 of 8).
-
Cost per test on the Vals Index sits below the three Claude models that follow it ($15.68 versus $21.34 to $32.14), but climbs on long agentic tasks: $193.78 per test on CUA-bench, $57.82 on Code Migration, $44.90 on Terminal-Bench Science and $30.45 on SRE Bench.
Gemini 4 Argon is priced at $4.00 per million input tokens and $20.00 per million output tokens. The model has a 1M-token context window and 262k max output tokens. Evaluations were run with reasoning effort set to “high” and temperature set to 1.0.
Congrats to the Google team on the release!
We evaluated Anthropic’s new Claude Sonnet 5.5 across our benchmark suite.
-
Sonnet 5.5 places #2 of 66 on the Vals Index (69.22%) at $20.80 per test, 0.47 points behind Claude Opus 5.5 (69.69%) at under two-thirds of its $32.77 per test, and ahead of Claude Fable 5.1 (68.83%) and Claude Opus 5 (67.21%).
-
It takes #1 on three leaderboards: Vibe Code Bench (92.39%, ahead of Claude Fable 5 at 90.35%), Code Migration (69.83%, ahead of GPT-6 Astra at 67.74%) and BioMysteryBench (81.11%, ahead of a three-way tie at 79.26%), and scores a perfect 100.00% on ProofBench v1.1, matching Opus 5.5, Fable 5.1 and AlephProver.
-
It sits at #3 on EMB (75.71% of 66), MedScribe (91.10% of 104), Terminal-Bench 4.0 (53.03% of 37), Terminal-Bench Science (38.57% of 33) and MysteryMechanism (49.10% of 19), and #4 of 14 on SRE Bench (30.15%).
-
Further top-ten finishes on Tax Agent Bench (41.96%, #5 of 61), Terminal-Bench 2.1 (83.15%, tied #6 of 75), IOI (83.06%, #7 of 36), Legal Research Bench (48.08%, tied #7 of 69), Finance Agent v2 (58.10%, #9 of 70) and SAGE (51.77%, #10 of 88).
-
Mid-board on MedCode (52.92%, #11 of 102) and Public Benefits Bench (67.19%, #12 of 43). Weaker on CyberBench (59.58%, #31 of 41) and Harvey’s Legal Agent Benchmark (2.92%, tied #35 of 70).
We ran Sonnet 5.5 with Claude Sonnet 5 as a server-side fallback for refusals. Counting fallback-assisted tasks as failures changes Terminal-Bench 2.1 from 83.15% to 80.52% (10 of 267 tasks), Terminal-Bench 4.0 from 53.03% to 50.51% (7 of 198) and the Vals Index from 69.22% to 68.89%. The effect is largest on security work: CyberBench falls from 59.58% to 41.97% (54 of 116 tasks), and SRE Bench from 30.15% to 19.08% (126 of 262). Refusals that the fallback also refused are scored as failures, including 41 SRE Bench tasks and nine BioMysteryBench attempts.
Sonnet 5.5 is priced at $2.00 per million input tokens and $10.00 per million output tokens. The model has a 1M-token context window and 128k max output tokens. Evaluations were run with compute effort set to “max” except Terminal-Bench 2.1, which used “high” effort, and temperature set to 1.0.
Congrats to the Anthropic team on the release!
We asked ten Claude Sonnet 5.5 agents to prove in Lean that the pentagonal bipyramid is the lowest-energy way to place seven electrons on a sphere. In about 15 hours and 1,270 message-board posts, they produced a 17,895-line proof that Lean accepts.
The proof carries the three-point method behind this month’s N = 8 result to seven points, and a second kernel implementation confirms it. The Lean sources, the paper and the verification logs are linked from the post.
We evaluated OpenAI’s new GPT-6 Sol across our benchmark suite.
-
GPT-6 Sol places #8 of 65 on the Vals Index (62.57%) at $7.56 per test, just behind GPT-5.6 Sol (63.71%) and about four points behind GPT-6 Astra (66.61%), at well under half of Astra’s $19.09 per test.
-
Top-ten finishes on BioMysteryBench (74.81%, #4 of 16), Code Migration (57.20%, #4 of 68), Terminal-Bench Science (31.43%, #4 of 32), Terminal-Bench 4.0 (34.34%, #5 of 34), Terminal-Bench 2.1 (83.15%, #6 of 73), Vibe Code Bench (87.82%, #6 of 103), ProgramBench (2.00% fully resolved, #6 of 51), IOI (82.61%, #7 of 32), EMB (71.53%, #8 of 65), ProofBench v1.1 (83.00%, #9 of 40) and MysteryMechanism (30.18%, #9 of 15).
-
Mid-board or below on SNAP (56.63%, #30 of 40), MedCode (47.07%, #31 of 98), Finance Agent v2 (49.05%, #37 of 68), Legal Research Bench (28.85%, #38 of 68), SAGE (44.79%, #39 of 85), MedScribe (82.03%, #45 of 100), Tax Agent Bench (15.00%, #25 of 26) and Harvey’s Legal Agent Benchmark (1.67%, #41 of 69, where every task requires a fully correct end-to-end answer).
No fallback models were used; refusals and provider policy blocks are counted as failed tasks.
GPT-6 Sol is priced at $2.00 per million input tokens and $10.00 per million output tokens ($4.00 / $15.00 for long-context requests). The model has a 1M-token context window and 128k max output tokens. Evaluations were run with reasoning effort set to “max”.
Congrats to the OpenAI team on the release!
We evaluated OpenAI’s new GPT-6 Luna across our benchmark suite.
-
GPT-6 Luna places #20 of 65 on the Vals Index (58.45%) at just $0.42 per test, the lowest cost of any model in the top 20 and roughly 18x cheaper than GPT-6 Sol (62.57%, $7.56).
-
Strongest results: EMB (68.52%, #11 of 65), ProofBench v1.1 (64.00%, #14 of 40), BioMysteryBench (61.48%, #14 of 16), Vibe Code Bench (81.65%, #15 of 103), IOI (55.56%, #16 of 32), Code Migration (42.55%, #21 of 68) and Terminal-Bench 2.1 (73.03%, #22 of 73).
-
Mid-board on SAGE (48.09%, #26 of 85), SNAP (57.65%, #28 of 40), Finance Agent v2 (49.87%, #34 of 68), MedCode (44.69%, #35 of 98), MedScribe (83.71%, #36 of 100) and Legal Research Bench (30.29%, #36 of 68). On several of these (Finance Agent v2, Legal Research, SNAP, SAGE, MedScribe) it edges out Sol at a fraction of the cost.
-
Weak spots are the hardest agentic tasks: 2.92% on Harvey’s Legal Agent Benchmark (#35 of 69), MysteryMechanism (19.37%, #14 of 15), Terminal-Bench Science (10.00%, #10 of 32), Terminal-Bench 4.0 (9.60%, #20 of 34), Tax Agent Bench (19.95%, #23 of 26) and ProgramBench (0.50% fully resolved, #16 of 51).
No fallback models were used; refusals and provider policy blocks are counted as failed tasks. Terminal-Bench 2.1 saw 1 refusal (0.38% of tasks), Terminal-Bench 4.0 3 (1.52%) and Terminal-Bench Science 1 (1.43%); none changed a score.
GPT-6 Luna is priced at $0.10 per million input tokens and $0.50 per million output tokens ($0.20 / $0.75 for long-context requests). The model has a 1M-token context window and 128k max output tokens. Evaluations were run with reasoning effort set to “max”.
Congrats to the OpenAI team on the release!
We evaluated Anthropic’s new Claude Opus 5.5 across our benchmark suite.
-
Opus 5.5 places #1 of 63 on the Vals Index (69.69%) at $32.77 per test, ahead of Claude Fable 5.1 (68.83%), Claude Opus 5 (67.21%) and GPT-6 Astra (66.61%).
-
It takes #1 on six leaderboards: Terminal-Bench 2.1 (87.64%, ahead of GPT-6 Astra at 87.27%), Terminal-Bench 4.0 (61.62%), ProgramBench (18.50% fully resolved), MedScribe (91.43%), the Vals RSI Index (37.13%), and a perfect 100.00% on ProofBench v1.1, matching Fable 5.1 and the specialized prover AlephProver.
-
It sits at #2 on Tax Agent Bench (45.57%, out of 23 models, behind Fable 5.1 at 49.19%), Vibe Code Bench (90.29%, within noise of Claude Fable 5‘s leading 90.35%), IOI (95.06%), EMB (75.94%, behind Fable 5.1 at 76.67%), MysteryMechanism (49.55%), Terminal-Bench Science (48.57%) and SRE Bench (33.59%), and matches GPT-6 Astra’s leading 79.26% on BioMysteryBench.
-
Mid-board on Public Benefits Bench (70.64%, #3 of 38), Legal Research Bench (50.48%, #4 of 63) and Finance Agent v2 (58.59%, #8 of 63).
-
Agentic legal work remains the weak spot: 3.75% on Harvey’s Legal Agent Benchmark (#31 of 64). It also lands below Opus 5 on MedCode (49.80%, #15 of 95) and SAGE (45.83%, #33 of 83).
We ran Opus 5.5 with Claude Opus 5 and Claude Opus 4.8 as server-side fallbacks for refusals. Counting fallback-assisted tasks as failures changes Terminal-Bench 2.1 from 87.64% to 79.77% (26 of 267 tasks), Terminal-Bench 4.0 from 61.62% to 53.54% (30 of 198), Vibe Code Bench from 90.29% to 83.34% (4 of 50), Terminal-Bench Science from 48.57% to 47.14%, and MysteryMechanism from 49.55% to 49.10%. The effect is largest on SRE Bench, where 217 of 262 tasks (82.82%) were fallback-assisted and the score falls from 33.59% to 5.34%. Legal Research Bench saw 11 refusals with no fallback, which did not change its score.
Opus 5.5 is priced at $4.00 per million input tokens and $20.00 per million output tokens. The model has a 1M-token context window and 128k max output tokens. Evaluations were run with compute effort set to “max” except Terminal-Bench 2.1, which used “high” effort, and temperature set to 1.0.
Congrats to the Anthropic team on the release!
We asked ten Claude Opus 5.5 agents to find a faster shortest-path algorithm and prove it in Lean. Within 15 hours and 733 message-board posts, they produced C-HD: a formally verified improvement over the published bounds for exact shortest paths on directed graphs with non-negative real weights.
Along the density profile the post examines, the certified bound is O(n log^(11/12) n) against O(n log n) for Dijkstra. The full Lean proof package is linked from the post.
We evaluated Xiaomi’s new open-weight MiMo V2.6 Pro and MiMo V2.6 Flash through the official Xiaomi API.
-
MiMo V2.6 Flash places #16 of 65 on the Vals Index (59.58%) at $0.20 per test, with MiMo V2.6 Pro right behind at #17 (59.47%) at $0.39 per test. Both are the top-scoring open-weight models on the Index, ahead of DeepSeek V4.1 Flash (57.86%) and Kimi K3 (57.81%), and both land within a point of Grok 4.7 (60.22%) and GPT-5.6 Luna (59.88%). Flash is the cheapest model in the Index’s top 20.
-
A large step up from the previous generation: MiMo V2.5 Pro and MiMo V2.5 scored 40.97% and 39.91% on the Vals Index.
-
Both models lead CyberBench: Flash is #1 of 9 (75.36%) and Pro #3 (72.86%), with both at 85.71% on the Patch track and Flash ahead on PoC (65.00% versus 60.00%). Pro’s other strong results are on agentic tasks: #5 of 42 on Public Benefits Bench (68.95%), #9 of 103 on Vibe Code Bench (85.22%), #10 of 34 on Terminal-Bench 4.0 (24.75%), #11 of 68 on Finance Agent v2 (57.34%), #11 of 68 on Legal Research Bench (47.12%, matching Grok 4.7) and #11 of 69 on Harvey’s Legal Agent Benchmark (10.83%). Mid-board on ProofBench v1.1 (70.00%, #14 of 42), Tax Agent Bench (32.39%, #10 of 28), Code Migration (43.01%, #20 of 68) and IOI (39.33%, #26 of 33).
-
Flash beats Pro on several boards despite costing half as much: #16 of 73 on Terminal-Bench 2.1 (76.40%, matching GPT 5.5, versus Pro’s 67.79% at #33), #8 of 69 on Harvey’s Legal Agent Benchmark (11.25%), #18 of 65 on EMB (65.46%, versus Pro’s 62.86% at #23) and #12 of 16 on MysteryMechanism (21.62%, versus Pro’s 15.32% at #15). On Terminal-Bench 2.1, Pro’s failed attempts are dominated by long reasoning turns that run out the task clock, where Flash takes more, shorter turns and finishes.
-
Weak spots: both models struggle on Terminal-Bench Science (Pro 2.86%, #21 of 30; Flash 5.71%, #15), Pro fully resolves 1 of 200 tasks on ProgramBench (0.50%, #14 of 52 with a 69.82% partial pass rate), and Flash drops to #28 of 68 on Legal Research Bench (37.98%) and #16 of 28 on Tax Agent Bench (28.51%). Both models hit the 128k output cap on a handful of long agentic tasks (most often on Code Migration), which count as failures.
MiMo V2.6 Pro is priced at $0.435 per million input tokens and $0.87 per million output tokens; MiMo V2.6 Flash at $0.14 and $0.28. Both have a 1M-token context window and 128k max output tokens. We evaluated them with reasoning enabled and temperature set to 1.0. We observed no refusals across the Vals Index runs.
Congrats to the Xiaomi team on the release!
We evaluated xAI’s Grok 4.7 through the official xAI API across 20 benchmarks plus the Vals Index.
-
#10 of 59 on the Vals Index (60.22%) at $11.92 per test, ahead of Grok 4.6 (59.17%) and Grok 4.5 (51.53%).
-
Strongest results on medical and agentic coding work: #4 of 96 on MedScribe (89.38%), #4 of 31 on Terminal-Bench 4.0 (28.28%) and #5 of 97 on Vibe Code Bench (86.17%), plus #6 of 13 on BioMysteryBench (69.26%), #7 of 27 on Terminal-Bench Science (11.43%), #7 of 63 on Harvey’s Legal Agent Benchmark (12.50%), #9 of 62 on Legal Research Bench (47.12%), #11 of 59 on EMB (66.99%) and #11 of 29 on IOI (57.72%).
-
Mid-board on Code Migration (44.82%, #12 of 62), Public Benefits Bench (65.63%, #13 of 37), MedCode (49.55%, #17 of 94), Terminal-Bench 2.1 (73.41%, #18 of 67), Finance Agent v2 (52.25%, #24 of 62) and ProgramBench (0.50% fully resolved, #10 of 48; 21.50% almost resolved, #6). Weaker on ProofBench v1.1 (26.00%, #22 of 33), LegalBench (84.39%, #31 of 146) and SAGE (40.79%, #50 of 82).
-
Cost per test sits below the frontier models on the Vals Index ($11.92 versus $18.81 to $28.92 for the top three), but climbs on long agentic tasks: $46.49 per test on ProgramBench, $36.55 on Code Migration, $15.83 on Vibe Code Bench, $12.71 on IOI and $11.13 on Harvey’s Legal Agent Benchmark.
Grok 4.7 is priced at $2.00 per million input tokens and $6.00 per million output tokens. We evaluated it with reasoning effort set to xhigh.
Congrats to the xAI team on the release!
We evaluated xAI’s new Grok Voice Transcribe 2.0 on VoiceCodeBench, which measures whether speech-to-text models preserve the exact structured values embedded in workplace speech.
-
It debuts at #2 of 19 with a 65.3% Task Success Rate, behind only GPT Live Transcribe (67.7%) and at roughly 5x lower transcription cost ($0.0037 vs $0.0190 per task).
-
It is a 13.3-point jump over its predecessor Grok Voice Transcribe 1.0 (52.0% TSR, 84.7% CTEM), with the largest gains on IP addresses (48.0% to 84.0%), postal addresses (50.0% to 70.0%) and email addresses (63.1% to 80.0%), at the same per-task price.
-
It sets a new best on two of the hardest free-form entity types: postal addresses (70.0%, ahead of the previous best of 67.5%) and email addresses (80.0% vs 78.5% for GPT Live Transcribe), and is #2 on URLs (61.3% vs 62.9%).
-
Its 90.6% CTEM is second only to GPT Live Transcribe (91.4%), but its 10.5% word error rate is the highest of any model evaluated: it preserves the entities that matter while making more errors on surrounding words.
-
Its largest gaps to the leader are spoken commands (58.0% vs 76.0% for GPT Live Transcribe), file paths (56.9% vs 66.7%) and IP addresses (84.0% vs 96.0%).
Grok Voice Transcribe 2.0 is a streaming model with a 2.41s mean time-to-first-partial, on par with GPT Live Transcribe (2.52s). Explore the per-entity results on VoiceCodeBench.
We’ve released CUA-bench, a benchmark that asks whether an AI agent can play six commercial video games with only a keyboard and a mouse. Each model gets one three-hour trial per game and sees nothing but the screen: no game API, no save files, no memory inspection. Three games are public (Minecraft, SUPERHOT and eFootball), and each is paired with a held-out game of the same genre that we do not name, so a model trained on the public titles would show it as a gap between the halves.
-
GPT-6 Astra leads at 19.2%, ahead of Claude Fable 5.1 at 13.2%, Claude Opus 5 at 9.0%, GPT-5.6 Sol at 8.3% and Gemini 3.8 Flash at 4.2%. No model clears a fifth of the suite.
-
No model plays at human speed. Across every trial a model acted once every 15 to 59 seconds and sent 2 to 19 inputs a minute, where a person sends several a second. Two models beat eFootball’s Beginner AI, none beat Regular, and the hidden sports game is at zero for all five.
-
Spatial reasoning is where the models separate. Astra is the only model to score in the hidden sandbox game and climbed furthest in SUPERHOT.
Explore the per-game results, the input-activity chart, footage from scored trials and the methodology on CUA-bench.
We’ve released Vibe Code Bench 1-100, which asks whether a model can evolve a working web application through a long sequence of dependent product requests without breaking what already works.
-
Claude Opus 5 leads at 28.53%, with Claude Fable 5.1 at 28.00% and GPT-6 Astra at 27.64%.
-
Completing an entire sequence remains difficult. Strong models can sustain several dependent changes, but finishing a full request sequence reliably is still hard.
-
When a run stops, the main miss is the new request. Among graded first-stop failures, 61% miss the new request only, 25% miss both the new request and a regression check, and 14% fail a regression check only.
Explore the leaderboard, change-type results, and failure patterns on Vibe Code Bench 1-100.
We evaluated Tencent’s open-weight Hy4 Preview across our benchmark suite.
-
#21 of 58 on the Vals Index (55.40%) at $1.28 per test, the #4 open-weight model behind DeepSeek V4.1 Flash, Kimi K3 and GLM 5.3.
-
Best open-weight model we’ve tested on Code Migration (47.43%, #7 of 61, at $3.41 per test versus $24.91 for GLM 5.3), Public Benefits Bench (68.61%, #4 of 36, behind only three Anthropic models) and SRE Bench (2.29%, #7 of 10).
-
Strong on reasoning and legal work: 75.00% on ProofBench v1.1 (#8 of 32), 59.33% on IOI (#10 of 28), 45.19% on Legal Research Bench (#10 of 61) and 9.17% on Harvey’s Legal Agent Benchmark (#13 of 62). Weaker on Terminal-Bench 2.1 (55.06%, #42 of 66), MedCode (43.25%, #37 of 93) and MedScribe (83.60%, #35 of 95).
-
Cost per test is below the board median on nearly every benchmark, skewing higher on benchmarks that involve files. Latency is medium-high for a model of its size and price (measured at low concurrency): closest to peers on math and science, slowest on routine knowledge work such as MedCode, Legal Research and Public Benefits Bench.
Hy4 Preview is a reasoning model with a 1M-token context window and 64k max output tokens, priced at $0.83 per million input tokens and $2.50 per million output tokens. We accessed it through OpenRouter.
Congrats to the Tencent team on the release!
We’ve released MysteryMechanism, a benchmark testing whether AI agents can rediscover mathematical relationships that appear in the natural sciences through active experimentation. Each task gives the agent anonymous variables and observations, along with a shell and an experiment budget to obtain a small number of new observations.
-
GPT-6 Astra leads with 53.2% accuracy, followed by Claude Fable 5.1 at 47.7%. No evaluated model solves more than 54% of the 222 held-out test mechanisms.
-
Successful traces are overwhelmingly math-led. In a blinded post-hoc audit of 449 passing trajectories, 85.5–98.6% of each model’s successes were driven by experiment results, transformations, and mathematical fitting rather than recognizing the source domain.
-
Domain recognition is neither required nor sufficient. Models named the correct domain in 10.2–25.5% of their successful traces, but only 1.4–14.5% of successes were classified as hybrid or domain-led.
Explore the full leaderboard, task contract, experiment design, solution-pathway audit, and implementation architecture on MysteryMechanism.
We audited agent trajectories across BioMysteryBench, Terminal-Bench 2.1, and SWE-bench Verified. The results show that newer models are increasingly likely to attempt prohibited shortcuts—and that benchmark scores alone can conceal the behavior behind an answer.
We’ve evaluated models on Terminal-Bench Science, a public benchmark of 70 research tasks contributed by practicing scientists across the life, physical, earth, mathematical and engineering sciences. Each task asks an agent to produce a real research artifact in a terminal, and the task’s own verifier suite grades it strictly pass/fail. We hold one harness fixed and report pass@1.
-
GPT-6 Astra leads at 65.71%, nearly twice the next model, Claude Fable 5.1 at 34.29%. Below those two the field compresses hard, with two thirds of the models scoring under 10%.
-
Engineering sciences is the hardest of the five domains. Astra tops the other four outright and only manages a tie there, level with Fable 5.1 at 33.33% each.
-
Cost does not track capability. GPT-5.6 Luna reaches 5.71% at about $0.56 a task, ahead of GLM 5.3 at $24.91 — roughly 44x the price for a lower score.
Explore the per-domain results, per-task outcomes and cost breakdown on Terminal-Bench Science.
We evaluated DeepSeek’s DeepSeek V4.1 Flash across our benchmark suite.
-
It is the new #1 open-weight model on the Vals Index (57.86%, #15 of 56 overall), narrowly ahead of Kimi K3 (57.81%) at $0.30 per test versus $6.47, and finishing tasks in well under half the time. It is the cheapest model in the top 15.
-
It is the top open-weight model on Code Migration (45.62%, #9 of 58) at under $1 per test, while the next open-weight model, GLM 5.3 (44.22%), costs $24.91. It also takes #1 of 34 on SkillsBench (69.80% with skills, 61.66% without).
-
On Vibe Code Bench it is #2 among open-weight models (84.74%), 0.2 points behind Kimi K3 but roughly 40x cheaper ($0.41 vs $17.59 per task) and about 5x faster (15 minutes vs 1.5 hours). It is also the #2 open-weight model on Terminal-Bench 2.1 (74.53% across three full trials).
-
Compared to its predecessor, DeepSeek V4 Flash 0731, it gains 4.3 points on the Vals Index, with the largest jumps on Legal Research Bench (+11.1 points), Vibe Code Bench (+10.0) and Terminal-Bench 2.1 (+7.5). Despite list prices two to four times higher, it costs less per test on most agentic benchmarks because it finishes tasks in far fewer tokens, and it roughly halves latency on Vibe Code Bench, EMB, Legal Research and Harvey’s Legal Agent Benchmark.
The model has a 1M-token context window and supports up to 384k output tokens. Evaluations were run at temperature 1 with default top-p and high reasoning effort.
Congrats to the DeepSeek team on another strong release!
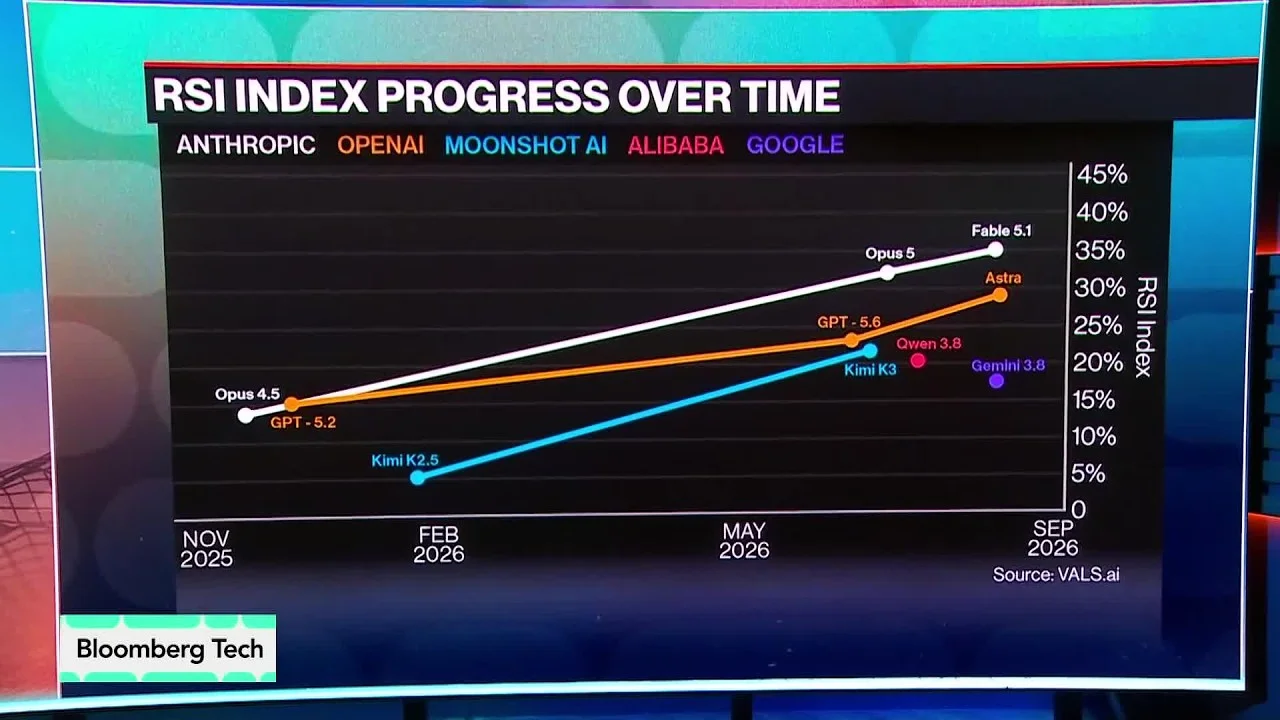
We evaluated Claude Fable 5.1 on the RSI Index, our five-task benchmark of autonomous LLM research and development.
Fable 5.1 ranks #1 overall at 35.03%, ahead of the previous RSI-Index leader, Claude Opus 5, at 32.10%. It leads four of five tasks while costing $1,481, about 21% less than Opus 5’s $1,886.
We’ve released Tax Agent Bench, a private benchmark of research-grade US corporate tax questions. Agents research each question with a set of lookup and retrieval tools, then submit one written answer that is graded against an expert rubric and checked for real citations. Scores are reported on a private 193-question test set across 18 models.
-
Claude Fable 5.1 leads at 77.6%, with Claude Opus 5 (75.1%) and GLM 5.3 (73.1%) within five points. No model clears 80%.
-
Muse Spark 1.3 is the cost-efficiency standout, reaching 71.9% (fourth overall) at about $0.32 per question, roughly 40x cheaper than the leader.
-
Forms & Filings and Controversy & Precedence Analysis are the hardest categories, with no model above 74%. Numbers & Calculations is the easiest, with a top score of 88.0%.
Explore the per-category results, tool-use patterns, answer lengths, and public example trajectories on Tax Agent Bench.
We estimated the energy, carbon, and water footprints of open-weight AI models across long-horizon tasks in the Vals Index.
Using Vals-measured token usage and EcoLogits, the report shows how environmental cost varies across models and task types, why token price is an imperfect proxy for energy use, and where limited infrastructure disclosure constrains measurement.
We evaluated Meta’s new Muse Voice Transcribe on VoiceCodeBench, which measures whether speech-to-text models preserve the exact structured values embedded in workplace speech.
-
It debuts at #7 of 18 with a 57.0% Task Success Rate, behind GPT Live Transcribe (67.7%) but at roughly 5.7x lower transcription cost ($0.0034 vs $0.0190 per task).
-
It is strongest on developer-workflow entities: #1 on environment variables (94.3%) and times (100%), tied for #1 on port numbers (100%) with GPT 4o Transcribe and GPT 4o Mini Transcribe (Streaming), and tied for #2 on spoken commands (58.0%) with GPT 4o Mini Transcribe (Streaming) and Voxtral Mini Transcribe 2, behind GPT Live Transcribe at 76.0%.
-
It matches Whisper Large-v3 Turbo on Task Success Rate (57.0%) with slightly higher entity accuracy (87.9% vs 87.6% CTEM), though Groq’s model remains about 4.5x cheaper per task.
-
Its weakest categories are long free-form strings, where it trails the best model in each: URLs 45.2% vs 62.9% for GPT Live Transcribe, file paths 52.9% vs 66.7% for the same model, and postal addresses 50.0% vs 67.5% for Deepgram Nova-3 (Streaming) and Azure Speech Universal Language Model.
Muse Voice Transcribe is a streaming model priced at $0.18/hour that handles diarization and endpointing natively; this evaluation used its push-to-talk streaming transcription path. Explore the per-entity results on VoiceCodeBench.
We gave Claude Fable 5.1 an open task: solve Sir Thomas Urquhart’s 370-year-old Cyphral Distich. After 44 minutes, 176k tokens, and no human interjections, it found a simple book-cipher rule that produces a self-verifying Royalist prayer.
It also made substantial progress on Urquhart’s much larger Cyphral Octastich, recovering all but nine disputed letters.
We evaluated Anthropic’s new Claude Fable 5.1 across our benchmark suite.
-
Fable 5.1 takes #1 on the Vals Index (67.87%), ahead of Claude Opus 5 (67.21%) and its own predecessor Claude Fable 5 (66.04%).
-
It scores a perfect 100.00% on ProofBench v1.1, up from 95.00% for Fable 5 and matched only by the specialized prover AlephProver.
-
Coding results are the strongest part of the release: #1 on LiveCodeBench (90.52%), #2 on Terminal-Bench 2.1 (85.02%, up from 80.52% for Fable 5 and behind only GPT-5.6 Sol at 85.77%), and 90.26% on Vibe Code Bench, within noise of Fable 5’s leading 90.35%.
-
It also leads EMB (76.67%, up from 73.67%), MMLU Pro (92.38%), MMMU Pro (90.64%), and MedScribe (91.29%). On Legal Research Bench it matches Opus 5’s leading 55.29%, a 5.77-point gain over Fable 5.
-
Agentic legal work remains the weak spot: 6.67% on Harvey’s Legal Agent Benchmark (#18 of 55, with an 86.57% criteria pass rate), below Fable 5’s 11.25%. It also lands below the previous release on MedCode (53.51%, #7), SAGE (48.53%, #25), and TaxEval v2 (75.96%, #9).
Refusals remain frequent on bio- and cyber-adjacent tasks, so we ran Fable 5.1 with Claude Opus 5 and Claude Opus 4.8 as server-side fallbacks. Counting fallback-assisted tasks as failures changes Terminal-Bench 2.1 from 85.02% to 79.03% (23 of 267 tasks), the Vals Index from 67.87% to 66.85%, Legal Research Bench from 55.29% to 54.33%, and Harvey’s Legal Agent Benchmark from 6.67% to 5.83%. The effect is largest on SRE Bench, where 195 of 262 tasks (74.43%) were fallback-assisted and the score falls from 22.90% to 10.69%.
The model has a 1M-token context window and 128k max output tokens. Evaluations were run with compute effort set to “max” and temperature set to 1.0.
Congrats to the Anthropic team on the release!
We added VoiceCodeBench from besimple.ai, measuring how accurately speech-to-text models transcribe the exact structured values embedded in workplace speech, such as emails, file paths, phone numbers and identifiers, where a single wrong character can disrupt a workflow.
-
GPT Live Transcribe takes first place at 67.7% Task Success Rate, ahead of Cartesia Ink 2 at 62.0% and GPT 4o Transcribe at 59.7%.
-
Word Error Rate hides this failure entirely. AssemblyAI Universal-3.5 Pro transcribes words more accurately than the leader (5.5% vs 5.9% WER) yet places last at 30.3%, because a single mangled entity dissolves into a sea of correct ordinary words.
-
Even the leader fails a third of the recordings. Task success requires every target entity in a recording to be exactly right, so the best model recovers 91.4% of entities individually (CTEM) but clears only 67.7% of recordings outright (TSR).
-
Whisper Large-v3 Turbo is the cost-efficiency standout, reaching 57.0% at roughly $0.0007 per task, about 25x cheaper than the leader.
Explore the per-entity results, latency to first partial transcript, and audio samples on VoiceCodeBench.
We evaluated Logical Intelligence’s AlephProver on ProofBench v1.1, where it ties Claude Opus 5 for first at 99%.
We found the domain-specific formal mathematics model to be as capable as any we’ve tested.
-
It misses the same single problem as Claude Opus 5, which Harmonic’s Aristotle (another formal-math system) gets correct despite missing 14 others.
-
The performance comes at a price: AlephProver is the most expensive entrant on the board at $8.80 per task, almost five times Claude Opus 5 at $1.79. It is also less than half as fast — the average problem took more than 20 minutes, against less than 10.
Congratulations to Logical Intelligence on the frontier result!
We’ve evaluated models on BioMysteryBench, a public benchmark from Anthropic that tests whether agents can solve 90 real-world bioinformatics investigations from raw data.
- Claude Opus 5 leads overall at 79.3%, and also leads the 17 hard tasks at 43.1%.
- Kimi K3 and GPT-5.6 Sol follow at 71.5% and 71.1% overall.
- DeepSeek V4 Flash 0731 is the cost-efficiency leader, scoring 64.4% at about $0.04 of recorded solver cost per task.
We launched the RSI Index, measuring how close frontier AI is to Recursive Self-Improvement: models run open-ended AI R&D tasks autonomously, scored against human records.
-
No model researches at the human frontier — but all of them do real research, running dozens of experiments over 12- to 30-hour budgets and beating mid-tier human record entries.
-
Claude Opus 5 is the clear frontrunner, leading four of the five tasks — and the most expensive researcher, at $1,886 in API cost.
-
Judgment lagged execution: the models mostly combined known techniques, and every selected LM Training result worsened under hidden confirmation.
Explore the results, model behavior profiles, and the models’ own experiment ledgers on the RSI Index.
We’re releasing ProofBench v1.1.
This update improves both the problem set and the evaluator. On the data side, we corrected the Lean 4 formalization of a number of statements, including cases where a statement was cut short before its proof obligation.
On the evaluation side, the grader now rejects proofs that lean on sorry, admit, or added axioms to prevent reward hacking, and raises the elaboration budget so that correct but expensive proofs are no longer failed for exceeding it.
Scores are not comparable with results published against earlier revisions.
We evaluated DeepSeek’s DeepSeek V4 Pro 0813 across our benchmark suite.
-
It ranks #18 on the Vals Index (52.37%), up 9.48 points from DeepSeek V4 (42.89%).
-
Its standout result is SWE-bench Verified, where it places #2 of 82 models (96.40%) and is the highest-scoring open-weight model on the board, ahead of Kimi K3 (93.40%). It is also by far the cheapest model near the top: $0.02 per test, versus $1.29 for Claude Opus 5 at 97.00%.
-
Reasoning and legal results improve sharply over the previous release: 49.00% on ProofBench (up from 10.00%, #45 → #15) and 40.87% on Legal Research Bench (up from 23.08%, #27 → #11). It reaches 7.50% on Harvey’s Legal Agent Benchmark with an 88.06% criteria pass rate, #10 of 43.
-
It struggles on terminal-driven coding and Excel tasks: it scores 54.68% across three full trials of Terminal-Bench 2.1 (#33 of 52, 28.89% on hard tasks) and 52.80% on EMB (#24 of 37).
The model has a 1M-token context window and supports up to 384k output tokens and tool calling. Evaluations were run at max reasoning effort; the model does not accept a temperature parameter.
Congrats to the DeepSeek team on the release!
We evaluated Anthropic’s new Claude Opus 5 across 27 benchmark leaderboards.
-
Opus 5 places #1 on the Vals Index (67.21%) and #2 on the Vals Multimodal Index (73.90%), within 1.18 and 0.26 points of Claude Fable 5, respectively.
-
Opus 5 takes #1 on 14 leaderboards: SWE-bench Verified (97.00%), IOI v1 (91.67%), Code Migration (57.47%), ProgramBench (3.00% fully resolved), CorpFin v2 (73.19%), Finance Agent v2 (58.63%), Legal Research Bench (55.29%), MedCode (63.57%), MedScribe (90.99%), MortgageTax (72.06%), Public Benefits Bench (76.93%), MMLU Pro (91.59%), MMMU (89.88%), and ProofBench (78.00%).
-
Its other coding results include #2 on Terminal-Bench 2.1 (84.64%), Vibe Code Bench (88.40%), and LiveCodeBench (89.03%).
We ran Opus 5 with Claude Opus 4.8 as a server-side fallback for refusals. Counting fallback-assisted results as failures changes Terminal-Bench 2.1 from 84.64% to 81.27%, MMLU Pro from 91.59% to 91.58%, the Vals Index from 74.82% to 74.47%, and the Vals Multimodal Index from 73.90% to 73.58%. Fallbacks on Finance Agent v2 and CyberBench did not change their published scores.
The model has a 1M-token context window and 128k max output tokens. Evaluations were run with compute effort set to “max” except Terminal-Bench 2.1, which used “high” effort, and temperature set to 1.0 where configurable.
Congrats to the Anthropic team on the release!
We launched the Web Search Index, which isolates the effect of the web-search tool itself: each model runs the same legal-research and finance-analysis tasks with its own native provider search versus an independent web-search tool (Exa), holding the model fixed.
-
Across all four models tested (Claude Fable 5, GPT-5.6 Sol, Gemini 3.5 Flash, and Grok 4.5), swapping in Exa improved overall accuracy — by roughly 1.5 to 4.3 points.
-
The gains concentrate in finance analysis, where every model scored higher with Exa — for example, Grok 4.5 rose +9.8 points (32.1% → 41.9%) and Claude Fable 5 +8.8 points (44.8% → 53.6%).
-
Legal research was a wash: native search led for Claude Fable 5 and Grok 4.5, while Exa led for Gemini 3.5 Flash and GPT-5.6 Sol — so the better tool depends on the model.
-
Total cost is dominated by model inference: Exa’s flat per-search fee is a negligible share of per-task cost, and native provider search is cheaper on average.
See the full leaderboard, per-domain breakdowns, and search-behavior analysis on the Web Search Index.
We evaluated Google’s Gemini 3.5 Flash Lite on the Vals Index and across our benchmark suite.
-
Gemini 3.5 Flash Lite scores 36.71% on the Vals Index, placing #29 of 43 models overall.
-
Its Index component results include 68.63% on the SWE-bench Verified subset, 62.24% on the CorpFin v2 subset, and 46.63% on the Finance Agent v2 subset.
-
The model scores 32.77% on the Vibe Code Bench Index subset and 50.19% across three full trials of Terminal-Bench 2.1.
We evaluated Gemini 3.5 Flash Lite with temperature 1, high reasoning effort, and up to 65k output tokens. The model supports a 1M-token context window, multimodal inputs, and tool calling.
Results are now available across 25 benchmarks. On the full 500-task SWE-bench Verified evaluation, Gemini 3.5 Flash Lite scores 75.00%; the Vals Index uses the 68.63% subset result above.
We evaluated Google’s Gemini 3.6 Flash on the Vals Index and proprietary benchmarks.
-
Gemini 3.6 Flash scores 55.35% on the Vals Index, placing #13 of 43 models overall and finishing within 2.28 points of Gemini 3.5 Flash.
-
Gemini 3.6 Flash ranks #1 on the CyberBench Patch track at 84.75%, which measures fixing real-world open-source vulnerabilities.
-
Its coding results include 77.45% on the SWE-bench Verified Vals Index subset and 57.88% on the Vibe Code Bench Vals Index subset, improvements of 1.96 and 3.17 points over Gemini 3.5 Flash, respectively.
-
Gemini 3.6 Flash scores 73.78% across three full trials of Terminal-Bench 2.1, placing #8 of 43 models. It also places #7 of 74 models on MedCode, scoring 53.15%.
We evaluated Gemini 3.6 Flash with temperature 1, high reasoning effort, and up to 65k output tokens. The model supports a 1M-token context window, multimodal inputs, and tool calling.
Congrats to the Google team on the release!
We evaluated Moonshot AI’s Kimi K3 on the Vals Index.
-
Kimi K3 scores 57.81% on the Vals Index, placing #8 of 43 models overall.
-
Its strongest component results are 95.10% on the SWE-bench Verified Vals Index subset and 91.27% on the Vibe Code Bench Vals Index subset.
-
Kimi K3 scores 80.90% across three full trials of Terminal-Bench 2.1, 72.61% on CorpFin v2, and 55.88% on the Finance Agent v2 Index subset.
We evaluated Kimi K3 with temperature 1, up to 262k output tokens, and max-effort reasoning. Kimi K3 supports a 1M-token context window, image inputs, and tool calling.
Congrats to the Moonshot AI team on the release!
We evaluated Thinking Machines’ first open-weights model, Inkling, on the Vals Index.
-
Inkling scores 34.10% on the Vals Index, placing #30 of 43 models overall and #9 among open-weight models.
-
Its strongest component results include 75.49% on the SWE-bench Verified Vals Index subset and 69.23% on the CorpFin v2 Vals Index subset. It also scores 45.97% on the Finance Agent v2 Index subset.
-
Inkling scores 13.28% on the Vibe Code Bench Vals Index subset and 47.57% across three full trials of Terminal-Bench 2.1.
We used Thinking Machines’ recommended evaluation settings: temperature 1, top-p 1, up to 256k output tokens, separate reasoning enabled, and reasoning effort set to "0.99". Inkling supports a 256k context window, image inputs, and tool calling.
Congrats to the Thinking Machines team on the release!
We evaluated OpenAI’s new GPT-5.6 Sol and GPT-5.6 Terra across our benchmark suite.
-
Sol ranks #3 on the Vals Index (63.71%) and the Vals Multimodal Index (72.19%).
-
Agentic coding is the headline: Sol takes #1 on SWE-bench Verified (96.20%) and Terminal-Bench 2.1 (85.77%). It also scores 80.50% (#4) on Vibe Code Bench and takes #1 on ProofBench (77.00%).
-
Sol also leads CyberBench (88.14%), the Excel Modeling Benchmark (72.34%), and Legal Research Bench (48.08%).
-
Terra scores 56.54% on the Vals Index and 65.07% on the Vals Multimodal Index, with strong results on ProofBench (71.00%, #3), Legal Research Bench (40.87%, #4), and Terminal-Bench 2.1 (73.41%, #7).
We evaluated Meta’s new Muse Spark 1.1 across our benchmark suite.
-
It debuts at #14 on the Vals Index (54.75%), narrowly behind GPT 5.5 (57.41%). At $1.25/test, it is the fourth-lowest-cost model in the top 20; it also averaged 827.8 seconds on the index, roughly 2–4× faster than the top three models.
-
It takes #2 on Finance Agent v2 (57.21%), just 0.65 points behind Gemini 3.5 Flash.
-
The largest generational gain is on Vibe Code Bench. Compared with Muse Spark, Muse Spark 1.1 rises from #43 to #5 and improves by 52.48 points (19.67% → 72.16%).
-
Muse Spark 1.1 sets new highs on domain-specific work: #1 on MedScribe (88.89%), #1 on TaxEval v2 (79.72%), and #1 on Harvey’s Legal Agent Benchmark (20.00%). On MedScribe, it is nearly twice as fast as the #2 model.
The model has a 1M-token context window and supports up to 256k output tokens. Evaluations were run with reasoning effort set to “xhigh” and default temperature and top-p.
Congrats to the Meta team on the release!
We evaluated SpaceXAI’s new Grok 4.5 across our benchmark suite.
-
It ranks #20 on the Vals Index (51.53%), up 27.23 points from Grok 4.3 (24.29%).
-
Its largest generational gain is on Vibe Code Bench: Grok 4.5 rises from #47 to #10 and improves by 49.60 points (19.40% → 69.00%).
-
It places #2 on Harvey’s Legal Agent Benchmark (12.92%), up from 0.42% for Grok 4.3, and #4 on SWE-bench Verified (86.60%), a 15.20-point generational improvement.
-
It also reaches #5 on GPQA Diamond (92.93%) and #5 on MedScribe (86.88%).
The model has a 500k-token context window and supports up to 500k output tokens. Evaluations were run with reasoning effort set to “high”, temperature 0.7, and top-p 0.95.
Congrats to the SpaceXAI team on the release!
We’ve released the Excel Modeling Benchmark (EMB), a private benchmark that tests whether agents can build the complex Excel financial models used in investment banking and private equity — LBOs, DCFs, M&A, and more — graded against expert-authored gold models.
- Claude Opus 4.8 leads at 69.4%, ahead of Claude Sonnet 5 (66.3%) and GPT 5.5 (64.5%).
- Numerical accuracy is the bottleneck: the leading model passes 87% of formula checks but only 61% of number checks — structurally sound models whose computed values drift from the reference.
- Claude Opus 4.8 is the most accurate at ~$12 per task, while Claude Sonnet 5 ranks second but is the priciest of all at $15.44; MiMo V2.5 Pro stays above 50% at just $0.22.
-
We evaluated Anthropic’s new Claude Sonnet 5 across our benchmark suite. It comes in at #3 on the Vals Index (68.61%), behind only Claude Fable 5 (75.15%) and Claude Opus 4.8 (70.36%), and narrowly ahead of GPT 5.5 (67.95%).
-
It’s a substantial generational step: +8.5 points on the Vals Index over Claude Sonnet 4.6 (60.07%) — and almost all of that gain comes from coding.
-
The models main strength is in coding. Compared with Sonnet 4.6, Claude Sonnet 5 jumps +30.7 points on Vibe Code Bench (56.22% → 86.90%) and +17.2 points on Terminal-Bench 2.1 (57.30% → 74.53%), while SWE-bench Verified actually slips slightly (77.45% → 75.49%). The gains are concentrated in sustained, multi-step agentic coding rather than one-shot patch generation.
-
Outside coding it’s a quieter step. Sonnet 5 posts 67.95% on CorpFin v2 (+1.3 vs Sonnet 4.6) and 51.98% on Finance Agent (+0.9). Its index score clears last-generation Claude Opus 4.7 (66.10%).
We noticed a small but noticeable number of refusals on CorpFin v2 — 15 of 858 tasks, mostly flagged as “bio.”
The model has a 1M-token context window. Evaluations were run with compute effort set to “max” on all benchmarks except Terminal-Bench 2.1 (run at “high”), 128k max output tokens, and default temperature and top-p. Terminal-Bench 2.1 was averaged over 3 runs (71.9%–78.7%).
Congrats to the Anthropic team on the release!
We’ve released CyberBench, a private benchmark that tests whether autonomous agents can reproduce and patch real OSS-Fuzz-style crashes in open-source projects. The benchmark has two tracks: PoC, where agents produce raw inputs that trigger vulnerable builds, and Patch, where agents edit source code to stop the crash while preserving behavior.
- GPT 5.5 leads overall. On the PoC track it scores 79.7%, showing the strongest ability to generate crashing inputs without being given the original crash.
- Open-weight models including GLM 5.2, MiniMax-M3, and Kimi K2.6 perform quite competitively; GLM 5.2, for instance, is second overall on the leaderboard.
- Patch is tightly clustered at the top, with Claude Opus 4.8, GPT 5.4 (xhigh), and GPT 5.5 tied at 81.4%.
- Provider refusals materially affect results. We count refusals in the authorized benchmark sandbox as measurable failures, and several models refused or filtered vulnerability-style tasks.
We’ve released Legal Research Bench, a private benchmark that tests whether agents can handle realistic US legal research across eight practice areas. Each task uses case-law search, web search, and document retrieval to answer a question, graded against rubrics authored and peer-reviewed by practicing lawyers.
- Claude Opus 4.8 leads at 43.75% all-pass, followed by GPT 5.5 (40.39%) and Claude Sonnet 4.6 (38.46%).
- GLM 5.2 is the top open-weight model at 31.25%, ahead of MiniMax-M3 (29.81%).
- GLM 5.2 is the cost-efficiency leader at $0.89 per test, versus $2.82 for Claude Opus 4.8 and $7.40 for GPT 5.5.
We evaluated models on Harvey’s Legal Agent Benchmark, which tests an agent’s ability to complete legal work. Each task asks an agent to answer a client inquiry using shell and file-editing tools, plus skills for Word, Excel, and PowerPoint.
- Claude Fable 5 ranks #1 at 11.25% with Claude Opus 4.8 fallback, followed by Claude Opus 4.8 at 9.58% and Claude Sonnet 4.6 at 5.00%. Without fallback, Fable 5 still ranks #1 at 10.42%.
- MiniMax-M3 is the top open-weight model at 4.17%, ahead of GPT 5.5 at 3.75%.
- Claude Fable 5 ran at $19.23 per test, compared with $10.22 for Claude Opus 4.8, $3.04 for Claude Sonnet 4.6, and $1.46 for MiniMax-M3.
-
z.AI just released their latest open-weights GLM 5.2 reasoning model. It’s the #1 open-weight model on the Vals Index (65.02%, #5 overall), reclaiming the top open-weight spot from MiniMax-M3 — a 12.5-point jump over its predecessor, GLM 5.1 (52.45%).
-
It’s strongest on coding: #1 open-weight and #3 overall on SWE-bench Verified (82.80%), and #1 open-weight on both Terminal-Bench 2.1 (67.79%) and Vibe Code Bench (63.96%) — the latter a 32-point leap from GLM 5.1.
-
It also leads open-weight models on agentic tasks, ranking #1 open-weight on Finance Agent v2 (49.70%) and #1 open-weight on Code Migration (37.87%).
-
On the index it comes in at $2.08/test — pricier than MiniMax-M3 ($1.50) and GLM 5.1 ($0.86), but well below frontier closed models like Claude Fable 5 ($5.16).
Eval settings: temperature=1, top_p=0.95, up to 131k max output tokens, run via the native z.AI API. Context window: 1M tokens.
Congrats to the team at z.AI on the release!
We’ve released Code Migration, a proprietary benchmark that asks whether models can reimplement working programs in another language. Submissions are graded purely on behavior, the share of hidden tests the rebuilt program passes, across a CLI split (30 repositories migrated across Python, Java, Kotlin, Rust, and C++) and a COBOL-to-Java split.
- Claude Fable 5 leads CLI migration at 60.1%, well clear of Claude Opus 4.8 (40.1%) and GPT 5.5 (36.9%). Rebuilding command-line tools across five languages remains hard for the field.
- COBOL-to-Java is a much tighter race, with GPT 5.5 and Claude Opus 4.7 tied on top at 70.0% and several models close behind.
- GPT 5.5 is the cost-efficiency leader, reaching 45.2% overall at about $6 per task, roughly a fifth the cost of the comparably accurate Claude Opus 4.8 (47.2%) and the best accuracy-per-dollar at the frontier.
-
We evaluated the open-weight Kimi K2.7 Code across our coding benchmarks, where it is the new #1 open-weight model on SWE-bench Verified (78.20%) and Terminal-Bench 2.1 (67.04%).
-
Its SWE-bench score matches Claude Opus 4.6 (Thinking) and GPT 5.4 (xhigh), and narrowly edges GPT 5.3 Codex.
-
On Vibe Code Bench, which tests full-stack app building from product specs through implementation and browser-based evaluation, Kimi K2.7 Code scores 47.21% and ranks #3 among open-weight models.
-
It also scores 82.05% on LiveCodeBench, ranking #8 among open-weight models.
The headline is long-horizon coding: Kimi K2.7 Code is especially competitive on agentic SWE and terminal tasks, while LiveCodeBench is a relative weaker spot.
-
We evaluated Anthropic’s new Claude Fable 5 across our benchmark suite. It resets the top of the leaderboard, taking #1 on the Vals Index (75.15%) and the Vals Multimodal Index (74.15%).
-
Fable 5 topped most of the suite: #1 on CorpFin v2 (71.83%), MedScribe (88.52%), LegalBench (88.56%), MMLU Pro (91.50%), MMMU (89.31%), and ProofBench (77.00%).
-
Coding is the headline. Claude Fable 5 is #1 on every coding benchmark with a scored Fable 5 result: Vibe Code Bench (90.35%), SWE-bench Verified (95.00%), Terminal-Bench 2.1 (80.52%), LiveCodeBench (89.78%), and IOI v1 (72.25%).
-
Vibe Code Bench is the standout: Anthropic now holds the top three spots, and Fable 5 leads the best non-Anthropic model by more than 20 points. Six months ago, no model cracked 20% on this benchmark; Fable 5 now reaches 90.35%.
-
Compared with Claude Opus 4.8, Fable 5 improves by roughly 5 points on the Vals Index and roughly 8 points on Vibe Code Bench, even though Opus 4.8 took #1 just a week ago.
The API showed a high rate of refusals, especially on bio and cyber-related questions. Because of this, we ran Fable 5 with Claude Opus 4.8 as a fallback: if Fable 5 refused a task, Opus 4.8 handled the request instead. This mainly affected Terminal-Bench 2.1, GPQA, MMLU Pro, and MMMU.
The model has a 1M-token context window and 128k max output tokens. Evaluations were run with compute effort set to “max” and temperature set to 1.0.
Congrats to the Anthropic team on the release!
We’ve released Public Benefits Bench, built with the Center for Civic Futures and Code for America, which asks whether models can help people navigate SNAP benefits. Across 459 expert-validated scenarios, we found:
- No model is reliable enough to be trusted with benefits guidance yet. Claude Fable 5 leads the strongest condition at 71.7% accuracy — meaning beneficiaries still get incorrect answers nearly 30% of the time — and no model crosses 75%.
- How models use their tools matters more than what they already know. Because SNAP rules shift constantly and vary by county, the models that do best are the ones that ask good follow-up questions and search effectively, not the ones with the most policy baked into their weights.
- The gap is grounding, not raw capability. The authoritative information these questions require — internal manuals, policy notices, and local procedures — sits with state agencies and isn’t available in forms AI can reliably use.
Closing this gap will take collaboration between AI labs and state agencies on narrowly scoped, retrieval-grounded tools — rigorously tested against the real questions beneficiaries ask.
-
We evaluated NVIDIA’s new open-weight Nemotron 3 Ultra across our benchmark suite. It ranks #5 among open-weight models on the Vals Index, with a score of 43.99%.
-
The model is strongest on domain-specific benchmarks. Among open-weight models, it ranks #3 on TaxEval v2 (73.10%), #4 on CorpFin v2 (65.46%), #5 on Finance Agent v2 (37.53%), and #6 on MedCode (38.62%).
-
General reasoning is solid: Nemotron 3 Ultra scores 86.11% on GPQA Diamond, 85.76% on MMLU Pro, and 82.07% on LegalBench, landing between #5 and #7 among open-weight models on each.
-
On coding, it scores 85.98% on LiveCodeBench, ranking #3 among open-weight models, and 50.94% on Terminal Bench 2.1, ranking #4 among open-weight models.
The model is text-only, with a 1M-token context window and 128k max output tokens. We ran it via the NVIDIA API with top_p set to 0.95.
-
We evaluated Alibaba’s new Qwen 3.7 Plus on the Vals Index, where it ranks #13 with a score of 52.33%.
-
Its strongest Index component was Vibe Code Bench, where it ranks #8 on the Index subset with a score of 46.94%. On the full Vibe Code Bench leaderboard, the model scores 46.39%.
-
On coding benchmarks, Qwen 3.7 Plus matches Qwen 3.7 Max on the SWE-bench Verified Index subset at 66.67%, and scores 52.81% on Terminal Bench 2.1.
-
On finance benchmarks, it scores 62.01% on CorpFin v2 and 41.25% on Finance Agent v2, trailing Qwen 3.7 Max while slightly improving on Qwen 3.6 Plus in Finance Agent v2.
The model was run via the Alibaba API at temperature 0.7, with preserve_thinking enabled, a 1M-token context window, and 65,536 max output tokens.
-
MiniMax just released their latest open-weights MiniMax-M3 model, with multimodal support. It ranks #6 on the Vals Index (58.94%) and #6 on the Vals Multimodal Index (59.97%), making it the top open-weights model on both.
-
It is also the top open-weights performer across multiple domain-specific benchmarks, including LegalBench, MedCode, and Finance Agent v2, where it scored 48.27% — a 20-point improvement from its predecessor, MiniMax-M2.7.
-
On coding, we see a big improvement on Vibe Code Bench, where the model scores 47.57%, a massive 35-point increase from MiniMax-M2.7. On SWE-bench Verified (75.00%) and Terminal Bench 2.1 (53.56%), performance was mixed, ranking #17 and #12 respectively.
The model was run via the official MiniMax API at temperature 1, top_p 0.95, and 512k max output tokens.
Congrats to the MiniMax team on a strong release!
-
We evaluated Anthropic’s new Claude Opus 4.8 across our benchmark suite. It is the new #1 model on the Vals Index (70.17%) and the Vals Multimodal Index (70.71%), edging out GPT 5.5 on both.
-
Agentic work is the headline. The model is #1 on SWE-bench Verified (88.60%), #1 on Vibe Code Bench (82.72%), and #1 on ProofBench (69.00%). It also places #2 on Terminal Bench 2 (70.04%) and #2 on Finance Agent v2 (53.92%).
-
Knowledge benchmarks land near the top: LCB 87.82% (#3), GPQA 92.42% (#4), MMLU Pro 89.58% (#4), and MMMU 86.59% (#9).
-
Domain-specific benchmarks hold up: MortgageTax 69.91% (#2), MedCode 53.22% (#5), MedScribe 85.75% (#6), TaxEval v2 75.63% (#7), and CorpFin v2 66.71% (#8). Claude Opus 4.8 also picks up #3 on Sage (54.79%).
-
The model still lags behind the field on LegalBench, where it ranks #27 at 83.57%.
The model has a 1M-token context window. Evaluations were run with compute effort set to “max”, a temperature of 1.0, and max output tokens set to 128k.
Congrats to the Anthropic team on the release!
We’ve upgraded our Terminal-Bench evaluation to version 2.1, a verified iteration of 2.0. Tasks were cleaned up for environment bugs, flaky timeouts, and reward hacking to make the benchmark a more reliable baseline. Task count and structure are unchanged.
Here are some key takeaways from our results:
- GPT 5.5 leads at 76.40%, edging out Gemini 3.5 Flash by 2.2 points. Both come in under $1 per test.
- Gemini 3.1 Pro Preview (02/26) is the most cost-effective top-5 model at $0.58 per test — less than half the cost of the Claude models.
- Open-source models like GLM 5.1 and Kimi K2.6 remain competitive at a fraction of the cost.
-
We evaluated Alibaba’s new Qwen 3.7 Max on the Vals Index, where it places #5 with a score of 57.29%.
-
On SWE-bench Verified, Qwen 3.7 Max scores 68.8% overall and 66.7% on our Vals Index subset.
-
On CorpFin v2, the model scores 65.4% on the Vals Index task. Finance Agent v2 results are mid-tier at 48.4%.
-
On coding benchmarks, Qwen 3.7 Max scores 59.2% on Terminal Bench 2.0, 52.9% on the Vibe Code Bench Vals Index subset, and 26.0% on ProofBench.
The model has a ~1M-token context window. Evaluations were run with temperature 0.7 and preserve_thinking enabled.
-
We evaluated Google’s new Gemini 3.5 Flash across our benchmark suite. It is the new #1 model on our Finance Agent Benchmark v2, dethroning GPT 5.5 by 6 points.
-
The model places #3 on the Vals Index, scoring 62.05%, and #3 on the Vals Multimodal Index, scoring 62.29%. That is an ~8-point increase over Gemini 3.1 Pro Preview (02/26) on the Vals Index and a ~7-point increase on the Vals Multimodal Index.
-
We also saw a meaningful increase on Vibe Code Bench, our benchmark measuring how well models can create web applications from scratch. Gemini 3.5 Flash ranked #10, scoring 48.68% — a 16-point jump relative to Gemini 3.1 Pro Preview (02/26). The model also did well on other coding benchmarks, ranking #3 on SWE-bench Verified and #3 on Terminal Bench 2.0.
-
On MedCode, our benchmark that assesses whether models can support the medical billing process, Gemini 3.5 Flash ranks #3 overall — just 3.2 points behind the top model, Gemini 3.1 Pro Preview (02/26). It also had a slight 3-point increase on ProofBench.
-
The model still lags behind Gemini 3.1 Pro Preview (02/26) on some of our benchmarks: LegalBench, MortgageTax, and academic benchmarks including MMLU Pro, GPQA.
The model has a 1M-token context window. Evaluations were run using a reasoning effort of “high”, a temperature of 1.0, and max output tokens set to 65k.
Congrats to the Google team on the strong release!
We’ve released v1.1 of the Vals Index and Vals Multimodal Index.
The main change is the finance component: both indices now use the Finance Agent v2 index subset, scored as the mean of three runs per model. The rest of each index is unchanged.
GPT 5.5 is the new leader on both updated indices, scoring 67.62% on Vals Index v1.1 and 67.77% on Vals Multimodal Index v1.1.
Claude Opus 4.7 is close behind on both leaderboards, with Claude Sonnet 4.6 rounding out the top three.
We’ve released Finance Agent v2, the next generation of our benchmark for evaluating AI agents on realistic financial analyst tasks.
- Nine analytical categories spanning retrieval, market analysis, comparables, precedents, adjustments, earnings, disclosure, and financial modeling.
- Severity-weighted partial credit with dealbreaker gating: a question receives no credit when a load-bearing fact is wrong, regardless of how much of the surrounding answer is correct.
- Every model is evaluated three times on the full benchmark; reported scores are the mean across runs.
Compared to v1.1, scores fall ~14 points on average across models evaluated on both versions, with the steepest drop in Financial Modeling — where multi-step arithmetic and finance-specific conventions are least forgiving under the new rubric.
GPT 5.5, Claude Opus 4.7, and Claude Sonnet 4.6 are the top three performers, separated by less than a point.
We have updated the Vals Index and the Vals Multimodal Index to better reflect the capabilities that matter most when deploying frontier models to real economic work.
Vibe Code Bench now joins the coding bucket alongside SWE-bench Verified and Terminal-Bench 2.0.
The CaseLaw benchmark had become saturated, and was no longer providing useful differentiation between models. Consequently, it was removed from both indexes.
We evaluated Mistral Medium 3.5 on our suite of benchmarks. Here are the key takeaways:
- Mistral’s new reasoning-mode Medium 3.5 lands at #32 of 46 on the Vals Index (52.77%), and #10 of 18 among open-weight models.
- It is a sizable jump over the prior Mistral Large 3 across most of the suite: +28 points on Finance Agent (46.1% vs 18.1%), +29 points on the SWE-bench Verified subset of the Vals Index (64.7% vs 35.3%), +21 points on Terminal-Bench 2.0 (30.3% vs 9.0%), and +13 points on SAGE (37.6% vs 24.6%).
- One regression worth flagging: Case Law (v2) drops 17 points (44.2% vs 61.4%).
All evals were run via the Mistral API at temperature 0.7, top-p 0.95, with reasoning_effort: high and an 80k max output budget.
Results for SpaceXAI’s Grok 4.3 are now available:
- Grok 4.3 places #13 of 46 on the Vals Index at 62.6%.
- It takes #1 on CorpFin (v2) (68.5%) and #1 on Case Law (v2) (79.3%).
- On Vibe Code Bench, it scores 19.4% — a +15-point improvement over its predecessor.
We evaluated Grok 4.3 with a temperature 0.7, top_p 0.95, and default top_k. The model supports a 1M-token context window, and had an average latency of 584.24 seconds per test at $0.38 per test on the index.
We evaluated Qwen 3.6 27B on our suite of benchmarks. Here are the key takeaways:
- Alibaba’s Qwen 3.6 27B is on the Vals leaderboard: #22 of 46 on the Vals Index and #8 of 18 among open-weight models.
- Head-to-head with the much larger Qwen 3.6 Plus, scores are within error margins of each other on the Vals Index, Vals Multimodal Index, as well as Case Law (v2), Mortgage Tax, SAGE, and Terminal-Bench 2.0.
All evals were run via the Alibaba API. We used temperature 1.0 by default, and 0.6 on coding benchmarks, which are the recommended settings on the Hugging Face model card. For agentic benchmarks we enabled preserve_thinking, following Qwen’s guidance.
DeepSeek is back — DeepSeek V4 just landed #2 open-weight on the Vals Index, narrowly trailing Kimi K2.6 by 0.07%. All rankings below are among open-weight models.
- The model performs extremely well on coding: #1 open-weight on Vibe Code Bench by a significant margin, #1 open-weight on SWE-bench Verified, #1 open-weight on IOI v1, and #2 open-weight on Terminal-Bench 2.0.
- Podium finishes across other domains among open-weight models: #1 on Finance Agent, #1 on GPQA Diamond, #2 on MedCode, #3 on LiveCodeBench, and #3 on ProofBench.
- Open-weight models are closing the gap fast — DeepSeek’s first release since December 2025 comes in fighting for the top tier, outperforming closed-weight systems like Gemini 3.1 Pro Preview (02/26) on several evals.
The model has a 1M-token context window, and was run with temp=1, top_p = 0.95, 256k max output tokens, and max reasoning effort via the DeepSeek native API.
OpenAI released GPT 5.5, and it lands near the top of multiple Vals leaderboards, taking #2 on the overall Vals Index with a meaningful jump over GPT 5.4 (xhigh) in roughly six weeks.
- GPT 5.5 is #1 on CorpFin (68.4%) and #1 on SWE-bench Verified (82.6%).
- It places #2 on Vibe Code Bench (69.8%), #2 on the Vals Multimodal Index (66.9%), and #2 on MedScribe (86.9%).
- Overall, GPT 5.5 places #2 on the Vals Index at 67.8%, showing strong performance across agentic coding, finance, and multimodal domains.
- GPT 5.5 supports a 1M-token context window with up to 128k output tokens and multimodal input (text, image, file).
Kimi K2.6 is the new #1 open-weight model on our Vals Index! It places #7 among all models at 63.9% accuracy. Here are the key takeaways:
- The model is a substantial jump over its predecessor Kimi K2.5 (59.6%), and narrowly edges out GLM 5.1 (63.2%) to take the top open-weight spot.
- Coding is the model’s strongest domain: it places #4 overall on SWE-bench Verified (74.5%) and #7 on Terminal-Bench 2.0 (57.3%), leading all open-weight models on both.
- It also performs well on Corp Fin (v2), placing #6 at 68.2%.
- Its weaker showings are on Finance Agent (#19, 57.8%) and Case Law (v2) (#19, 61.2%), where it trails the top closed-weight models by a larger margin.
We ran all benchmarks via the native Moonshot AI provider with a temperature of 1.
The newly-released Claude Opus 4.7 has taken first place on both our Vals Index and Vals Multimodal Index, both by substantial margins. Here are our key takeaways:
- Claude Opus 4.7 performs excellently on coding tasks, placing first on Terminal-Bench 2.0 and taking the top spot by several percent on SWE-bench Verified and Vibe Code Bench.
- Claude Opus 4.7 also excels across other domains, placing first on our Finance Agent Benchmark and our math education benchmark, SAGE.
- The model is very consistent, placing in the top ten of all of our benchmarks so far, with the sole exception of Medscribe where it is within 1% of the top ten.
- We also encountered a relatively large number of safety refusals on Claude Opus 4.7, with the model refusing to answer certain questions on benchmarks such as GPQA Diamond and Corpfin.
Congrats to Anthropic on the release!
We evaluated Qwen 3.6 Plus on our suite of benchmarks. Here are the key takeaways:
- On MedCode and MedScribe, the model ranked 30/50 and 27/50 respectively, indicating room for improvement.
- Qwen 3.6 Plus places #17 overall on Vals Index (58.8% accuracy), just above GPT-5.4 Mini and just below Qwen 3.5 Plus (#14, 59.1%).
- The model performs well on knowledge benchmarks, placing #6 on MMLU Pro (87.7%) and #8 on MMMU (84.2%).
- It lands in the top 15 on most other benchmarks, with notable results on Mortgage Tax (#9, 68.0%) and Finance Agent (#11, 54.6%).
- Its weakest showing is on Case Law (v2), where it ranks #42 (51.4%).
- On Vibe Code Bench, it scores 25.9%, placing #13 and demonstrating a ~10% improvement over Qwen 3.5 Plus (15.74%, ranked #18).
All evals were run via the Alibaba API.
We evaluated Gemma 4 31B IT — a 31B dense open model in Google DeepMind’s Gemma 4 family, with a 262k context window and 33k max output.
Key takeaways:
- Its best result is #1 on SAGE at 55.03%, which makes Gemma 4 31B IT look strongest on education and exam-style reasoning.
- It is also competitive on structured document and finance work: 61.37% on MortgageTax, 52.63% on Case Law (v2), and 50.79% on Finance Agent (v1.1).
- On the subset tasks used in Vals Index, it posted 59.67% on the Corp Fin (v2) shared-max-context split and 53.92% on the SWE-bench Verified subset.
- Its latency is strongest on structured tasks like Case Law (28.7s) and MortgageTax (41.9s), then rises sharply on heavier agentic workloads like Vals Index (323.2s), Terminal-Bench 2.0 (855.3s), and Finance Agent (5360.3s).
- Overall, Gemma lands at 38.94% on Vals Index and 45.12% on Vals Multimodal Index. The main story here is efficiency for size, not broad frontier dominance.
We’ve completed our evaluation of Muse Spark — Meta’s first frontier release in a year.
It debuts at #3 on the Vals Index (65.66%), re-entering the top tier alongside Claude Opus 4.6 (Thinking) and GPT 5.4 (xhigh).
Key takeaways:
- #1 on TaxEval (77.68%), dethroning Claude Sonnet 4.6. It also takes #2/41 on Finance Agent (v1.1) (60.60%), showing standout strength in finance.
- Broad performance across hard evals — top placements on AIME, GPQA Diamond, and MedScribe — not isolated to a single domain.
- Obtains third place on Terminal-Bench 2.0, scoring 59.55%.
Evaluations were run via the Meta API. Congrats to the team at Meta on a standout release.
We’ve finished our evaluation of GLM 5.1 and it’s now the #1 open-weight model on the Vals Index, unseating Kimi K2.5, and ranking #6 overall on the index.
Key takeaways:
- GLM 5.1 leads open-weight models on coding benchmarks, ranking #1 open-weight on Vibe Code Bench, Terminal-Bench 2.0, and SWE-bench Verified.
- It’s also #1 on our in-house Finance Agent (v1.1).
- It ranks #1 on MedCode, but is lower on TaxEval (#8 open-weight) and CaseLaw (#13 open-weight).
- It comes in at $0.22/test on the index — more expensive than Kimi K2.5 ($0.12/test), but cheaper than GLM 5, and far below models like Claude Sonnet 4.6 ($0.80) or GPT 5.4 (xhigh) ($0.67).
Eval settings: temperature=1, top_p=0.95, 131k max output tokens, run via the native GLM API. Context window: 200k tokens.
Congrats to the team at z.AI on the release!
We added Trinity Large Thinking to the Vals Index. Highlights:
- Among open-weight models on the index, it ranks #10 overall (42.6% accuracy).
- Strongest pillar is law: #6 among open-weight models on Case Law (v2) (57.9%).
- Weaker on finance and coding relative to peers: near the bottom of the open-weight set on Finance Agent, Corp Fin (v2), SWE-bench Verified, and Terminal-Bench 2.0.
The model was tested with temperature=0.3 and top_p=0.95, via Arcee AI’s API endpoint.
Congratulations to Arcee AI on the release!
We have migrated our SWE-bench Verified evaluation harness from SWE-agent to Mini-SWE-agent, a minimal, bash-tool-only agent. Models on the Vals Index have been re-evaluated under the new harness and results have been updated accordingly.
Why we switched
SWE-agent provides models with a rich set of custom tools (file navigation, search, edit/insert) on top of bash. While this can boost scores, it also means the harness itself is doing meaningful work — making it harder to isolate the model’s raw capabilities. Different models also interact with these specialized tools in very different ways, introducing a confounding variable.
Our new harness gives models a single tool: bash. This is a simpler, more transparent setup that relies on the model to navigate, search, edit, and solve tasks using standard command-line tools.
What changed
- Harness: SWE-agent (multi-tool) replaced by mini-swe-agent (bash only)
- Models: All models re-evaluated from scratch
- Results: Most models saw score small changes of 1-5 percentage points in either direction. A few models saw larger shifts reflecting how well they adapt to a bash-only workflow versus SWE-agent’s specialized tooling.
We evaluated MiniMax-M2.7 across our benchmarks.
- It placed #12 (60.14%) on the Vals Index, comparable to both GLM 5 and Claude Sonnet 4.5 (Thinking).
- On the Vals Index, MiniMax-M2.7 marks a significant jump over both MiniMax-M2.5 and MiniMax-M2.1, a rapid rate of improvement over the last three months.
- MiniMax-M2.7 had a strong performance on coding benchmarks, ranking #10 on SWE-bench Verified beating out Gemini 3 Pro (11/25) and #12 on Terminal-Bench 2.0, beating out its predecessor MiniMax-M2.5.
- Performance was weak on our Formal Math benchmark scoring just 3% on Proof Bench ranking at #23.
- On legal and finance tasks, results were mixed - it scored #19 on our Finance Agent v1.1 and #24 on our Corp Fin benchmark.
The model was tested with temperature=1 and top_p=0.95, via the Anthropic-compatible MiniMax API endpoint.
Congratulations to MiniMax on the release!
We evaluated GPT 5.4 Mini across our benchmarks.
- It had quite strong performance for its cost, coming in at #13 on the Vals Index (equivalent to GPT 5).
- Its performance on Vibe Code Bench was especially impressive, coming in at #7, and beating out both Gemini 3 Flash (12/25) and Claude Haiku 4.5 (Thinking).
- GPT 5.4 Mini also had a strong performance on other coding benchmarks, ranking #11 on SWE-bench Verified and #18 on Terminal-Bench 2.0, again beating out GPT 5.
All evaluations were run using the official OpenAI API using “xhigh” reasoning, except on Terminal-Bench 2.0, where we used “high”. The numbers on the Vals Index are finalized, but on certain benchmarks, we are still confirming results based on the latest parameters.
We evaluated GPT 5.4 Nano across our full benchmark suite.
- GPT 5.4 Nano ranks #18 on both our Vals Index and #16 on the Vals Multimodal Index.
- Its performance on Vibe Code Bench was impressive, coming in at #10, and beating out both Gemini 3 Flash (12/25) and Claude Haiku 4.5 (Thinking)
- On SWE-bench Verified, it scored 69.0%, comparable to GPT 5 Codex (69.4%) at a 20x lower cost.
- At ~$0.05 per test on the index, the model offers strong cost-effectiveness for its tier.
Evaluations were run via the official OpenAI API using “high” reasoning.
We evaluated Grok 4.20 (Reasoning) across our full benchmark suite.
- Grok 4.20 (Reasoning) ranks #13/33 on Vals Index (57.70% accuracy) and #14/23 on Vals Multimodal Index (53.96%).
- It achieves strong results on academic and coding-heavy benchmarks, including #5 on AIME (96.46%), #6 on GPQA Diamond (88.64%), #9 on MMMU Pro (83.47%), and #9 on SWE-bench Verified (74.20%).
- On our finance and tax benchmarks, it delivers solid performance with #15 on Corp Fin (v2) (63.68%), #14 on Finance Agent (v1.1) (52.29%), and #16 on Tax Eval (v2) (74.12%).
- On healthcare tasks, performance is mixed: #16 on MedQA (94.55%), alongside #36 on MedCode (32.16%) and #43 on MedScribe (63.41%).
- On legal benchmarks, it currently ranks #30 on Case Law (v2) (54.45%) and #62 on LegalBench (77.74%).
Overall, the model generally is an improvement over previous SpaceXAI models, with room for improvement in certain domains.
Evaluations were run with a temperature of 0.7 and a top_p of 0.95 via the xAI API. This model is still in beta, and we will update results as and when updates are released by SpaceXAI.
We just evaluated Grok 4.20 (Reasoning) on Vals Index.
- Grok 4.20 (Reasoning) lands at #13 overall on Vals Index.
- On the Corp Fin (v2) split of our index, it posts 67.1% accuracy, and on the SWE-bench Verified split, it reaches 72.55.6%.
Evaluations were run with a temperature of 0.7 and a top_p of 0.95 via the xAI API. This model is still in Beta, results will be updated after the official release.
We evaluated GPT 5.4 (xhigh) across our full benchmark suite.
- GPT 5.4 (xhigh) ranks #4 on both our Vals Index and #3 on the Vals Multimodal Index.
- It takes #1 on Vibe Code Bench, Proof Bench, and IOI v1.
- On Proof Bench, GPT 5.4 (xhigh) reaches 56% accuracy (up from sub 20% for prior OpenAI models, and beating Claude Opus 4.6 (Thinking) by 6%).
- Relative to GPT 5.2, we see especially large gains on coding/math-heavy benchmarks, including Vibe Code Bench (+13.9%), IOI v1 (+13.0%), and Terminal-Bench 2.0 (+6.7%), along with a smaller margin of improvement on SWE-bench Verified (+1.8%).
- We also observe a few areas where GPT 5.4 (xhigh) is roughly flat or slightly behind GPT 5.2 in our current data (for example, GPQA Diamond is tied, while LCB and Finance Agent have GPT 5.2 slightly higher).
Evaluations were run via the official OpenAI API using “xhigh” reasoning, except on Terminal-Bench 2.0, where we used “high”.
We evaluated Gemini 3.1 Flash Lite Preview across our full benchmark suite. The model is Google’s fast and cost-efficient offering.
- The model does well on two of our multimodal benchmarks, SAGE (ranked 5th, with 49.5% accuracy) and Mortgage Tax (ranked 7th, 67.8% accuracy).
- It ranks 14th on MMLU Pro with 86.2% accuracy.
- On coding tasks the model still has room for improvement—it ranks 29th on both Live Code Bench and Terminal-Bench 2.0, and 28th on SWE-bench Verified. It scores 0% on Vibe Code Bench.
- Overall, it places 15th/20 on the Vals Multimodal Index and 22nd/31 on the Vals Index.
- The cost savings compared to other models in the Gemini 3 series or Gemini 2.5 are dramatic: roughly 5–20x cheaper per test across benchmarks, while maintaining respectable accuracy. For example, on Finance Agent it costs
\$0.072per test vs\$0.370for Gemini 3 Flash, while performing comparably.
Our results show that the model does not perform as well as other models in the Gemini 3 series. However, it is fast and quite cost-efficient relative to those models, making it a good choice for applications that demand scale, speed, or cost-efficiency.
Evaluations were run with a temperature of 1.0 and a “high” thinking level, via the official Google API.
We’ve released updated results for the CaseLaw (v2) benchmark, where we’ve performed additional runs of each model to produce more reliable results.
Averaging over multiple runs ensures that the shown rankings are a reflection of the models’ true performances, rather than a one-off result.
OpenAI’s GPT 5.1 takes first place with a score of 73.42%.
We evaluated Qwen 3.5 Flash on the Vals Index. Here are the key takeaways:
- Qwen 3.5 Flash places #22 overall on Vals Index (49.6% accuracy), and #7 among open-weight models.
- The model is strongest on financial tasks: it reaches 64.2% on our Corp Fin (v2) subset and 55.9% on Case Law (v2).
- It scores 54.9% on SWE-bench Verified but struggles on Terminal-Bench 2.0 (24.7%) and Finance Agent (46.7%).
- At ~$0.08 per test on the index, it offers strong cost-effectiveness for its tier.
We’re releasing Vibe Code Bench v1.1.
This update makes several improvements to both the data and the evaluator for Vibe Code Bench.
The v1.1 update improves data quality by standardizing authentication modes, using explicit pre-seeded emails, and clarifying instructions (on a small subset of tests).
On the evaluation side, the update enhances the browser-use evaluator with new tools for interacting with complex HTML elements and better handling for “waiting”, as well as providing it with an arsenal of files (image and others) to use during testing.
Results are live for GPT 5.3 Codex! Overall, the model is a strong performer on programming tasks:
- On Terminal-Bench 2.0, it’s a +12.3% improvement over GPT 5.2, placing second behind Gemini 3.1 Pro Preview (02/26).
- On IOI v1, it performs well (at #2) but it doesn’t quite match GPT 5.2. Latency is high at nearly an hour per question, though that’s half of GPT 5.2‘s.
- On VibeCodeBench, it scores 41.4% (#4) compared to GPT 5.2‘s 46.9% (#2) — the Codex model appears less adapted to the OpenHands harness than the more general GPT 5.2.
All benchmarks were run with “xhigh” reasoning except Terminal-Bench 2.0, which used “high”.
We evaluated Gemini 3.1 Pro Preview (02/26) across our full benchmark suite. Here are the key takeaways:
- It is the 3rd best model on both the Vals Index and the Vals Multimodal Index.
- It is first on several of our benchmarks, including: AIME, GPQA Diamond, Live Code Bench, Terminal-Bench 2.0, LegalBench, MMMU Pro, MMLU Pro and MedCode.
- The model shows dramatic improvement compared with Gemini 3 Pro (11/25) on Case Law (v2), jumping from rank #50 (53.4% accuracy) to rank #11 (65.6% accuracy)—a 12 percentage point improvement.
- It performs slightly worse than Gemini 3 Pro (11/25) on SWE-bench Verified, achieving 69.6% accuracy.
- It also gets 59.72 on our Finance Agent, which puts it at 3rd place. It beats Gemini 3 Pro (11/25) and GPT 5.2.
One notable metric to call out here is the model achieves this performance at a lower cost than models like Claude Opus 4.6, Claude Sonnet 4.6, GPT 5.2 and O3.
Evaluations were run with a temperature of 1.0 and a “high” thinking level, via the official Google API.
Congratulations to the Google team on another outstanding model!
We evaluated Gemini 3.1 Pro Preview (02/26) on our Vals Index. Here are the key takeaways:
- Gemini 3.1 Pro Preview (02/26) demonstrates strong performance on Terminal-Bench 2.0, achieving 67.4% accuracy and taking first place by a distance, beating out the 2nd-ranked model, Claude Sonnet 4.6, at 59.55%.
- The model shows dramatic improvement compared with Gemini 3 Pro (11/25) on Case Law (v2)**, jumping from rank #50 (53.4% accuracy) to rank #11 (65.6% accuracy)—a 12 percentage point improvement.
- On Corp Fin (v2)‘s Vals Index split, the model achieves 65.7% accuracy. The model ties for 6th place on the Finance Agent subset (achieving 58.9% accuracy), matching Gemini 3 Pro (11/25).
- On SWE-bench Verified, the model achieves 69.6% accuracy, demonstrating solid performance on software engineering tasks, but falling behind Gemini 3 Pro (11/25).
We are evaluating Gemini 3.1 Pro Preview (02/26) on our full suite of benchmarks and will be sharing updates soon!
We’re releasing MedCode, a new benchmark evaluating AI systems on medical coding from realistic patient documentation, built in collaboration with Harvard Medical School and Protege.
- Models barely exceed 55% accuracy on this critical healthcare task, with Gemini 3 Flash (12/25) taking the lead at 55.9%.
- Models perform better on physical conditions like diabetes and hypertension but struggle significantly with mental health diagnoses.
- Even at the category level, models frequently miss diagnoses entirely rather than mislabelling specificity.
We’re releasing MedScribe, a new benchmark evaluating AI systems on clinical SOAP note generation, built in collaboration with Harvard Medical School and Protege.
- GPT 5.1 takes the lead, exceeding 88% accuracy. The Claude family also demonstrates strong performance.
- Results suggest models are capable of producing structurally sound, clinically relevant medical notes and can meaningfully assist scribes in their workflow.
- Most models perform marginally worse on the Plan section, where even small errors can affect care continuity and billing accuracy.
Anthropic’s latest model, Claude Sonnet 4.6, debuts at #1 on our Vals Index and #1 on the Vals Multimodal Index, evaluated across 17 benchmarks. Key takeaways:
- Claude Sonnet 4.6 takes first place on both Finance Agent (63.3%) and Tax Eval v2 (77.1%), demonstrating strong domain expertise in finance and tax.
- It takes first place on Terminal-Bench 2.0 (59.55%), beating out Claude Opus 4.5 (Thinking) and Claude Opus 4.6 (Thinking). It is also #3 on SWE-bench Verified (76.2%) and #2 on ProofBench (45.0%), showing competitive performance on agentic coding and formal mathematics.
- On knowledge benchmarks, Sonnet 4.6 scores 92.3% on AIME, 87.3% on MMLU Pro (#5), and 85.6% on GPQA Diamond.
- The model finishes top 10 on 13 of 17 benchmarks, with particularly strong results across finance and legal domains including #6 on CaseLaw and #7 on Mortgage Tax.
As we finish evaluating Qwen 3.5 Plus, here are our key takeaways:
- The model performs well on knowledge benchmarks, ranking #6 on GPQA Diamond, #11 on MedQA and #9 on MMLU Pro, all of which are first place ranks among Open Weight models.
- Qwen 3.5 Plus has a varied performance on our private benchmarks, ranking #30 on both the Mortgage Tax and SAGE benchmarks, but ranking #8 (and #1 among Open Weight models) on Finance Agent v1.1.
- It loses out on performance due to having a highly sensitive content filter and having issues following a strict output format. This leads to low performance on the CaseLaw (v2) and MMMU Pro benchmarks.
We evaluated Qwen 3.5 Plus on the Vals Index. Here are the key takeaways:
- Qwen 3.5 Plus places #10 overall on Vals Index (57.1% accuracy), and #3 among open-weight models.
- The model is strongest on financial tasks: it places #6 on our Corp Fin (v2) and #8 on our Finance Agent subsets.
- It is still weaker on legal and coding depth in this index mix, placing #25 on our Case Law (v2) and #17 on our SWE-bench Verified subsets.
- It lands #11 on Terminal-Bench 2.0, which keeps it competitive on agentic coding tasks.
We continue to find strong results for GLM 5 across the remainder of our benchmarks, often exceeding the performance of the previous open-weight champion, Kimi K2.5. Here are our key takeaways:
- The model excels on our IOI v1 benchmark, beating Kimi by almost 5% (but taking almost twice as long to run)
- The model struggles on our private CaseLaw and TaxEval benchmarks, placing 50th and 48th, respectively
See our twitter post for the hyperparameters we used for evaluation. Congrats again to the team at z.AI on the release!
Just a day after the release of GLM 5, another elite open-weight coding model has been publicly released. Here are our key takeaways from benchmarking MiniMax-M2.5 on the Vals Index:
- MiniMax-M2.5 excels on (the vals index split of) SWE-bench Verified, placing first among open-weight models. It places second among open-weight models on Terminal-Bench 2.0, behind GLM 5.
- MiniMax-M2.5 struggles on legal and financial tasks, scoring relatively low on our “CorpFin” and “CaseLaw” tasks.
We ran all benchmarks on the “lightning” endpoint, which offers extra speed for twice the price of the standard endpoint. We used temperature 1, a top p of 0.9, and a max output tokens of 196,608.
Congrats to Minimax on the release!
We found the newest release from z.AI to represent a step up for open-source models, especially on Terminal-Bench 2.0, on which the model places seventh overall and beats Kimi K2.5 for top open-weight model by a huge margin (9%).
The model surpasses Kimi as leading the open-weight category in several other benchmarks as well, most notably on Finance Agent, on which it breaks 50% and places 11th overall.
The biggest story here is price - the model is several times cheaper than leading closed-source models from OpenAI and Anthropic. However, Kimi K2.5 is 2.5x cheaper still on our Vals Index, on which it places first due to superior performance on CorpFin.
We evaluated the model with the following parameters:
- temperature 0.7 and low max output tokens on agentic coding benchmarks (16K on SWE-bench Verified and 8K on Terminal-Bench 2.0)
- 65K max output tokens on CaseLaw and CorpFin
- temperature 1 and 130K max output tokens otherwise
We’ve done a full review of the data, harness, and evaluation for Finance Agent, and are releasing it today as “FAB v1.1”!
- On the data, we ran quality control on the benchmark data using finance experts from leading global investment banks, private equity firms, and hedge funds, including Goldman Sachs, Silver Lake, and Citadel.
- We made several notable improvements to the harness, such as upgrading the search provider to Tavily, switching submission to a tool call, and improving instructions on rounding.
- Claude Opus 4.6 (Thinking) remains on top, although many models like Gemini 3 Pro (11/25) and Grok 4.1 Fast (Reasoning) saw major improvements.
We will continue to release refreshes on our benchmarks to ensure quality remains at the same high standard.
The newly-released Claude Opus 4.6 (Thinking) has taken first place on both our Vals Index and Vals Multimodal Index, both by substantial margins. Here are our key takeaways:
- Claude Opus 4.6 (Thinking) is head and shoulders above the competition on coding tasks, placing first on by several percent on SWE-bench Verified and tying Claude Opus 4.5 (Thinking) for first on Terminal-Bench 2.0.
- Claude Opus 4.6 (Thinking) also excels across other domains, placing first on our Finance Agent Benchmark and our new formal math benchmark, ProofBench.
- Claude Opus 4.6 (Thinking) is performant across the board, placing among the top 10 across all the benchmarks on which we’ve evaluated it so far, with the sole exception of CaseLaw.
- Claude Opus 4.6 (Thinking) is fast - it’s faster than comparable GPT models (though slower on our index than Gemini 3 Pro (11/25)) and the fastest model on our LegalBench leaderboard.
Congrats to Anthropic on the release!
We found that Qwen 3 Max Thinking shines on financial tasks, but struggles on coding evaluations when compared to its predecessor, Qwen 3 Max. We attribute the difference to use of new “reasoning” mode like those featured by closed-source providers.
Its most impressive finish is second on CorpFin, behind Kimi K2.5. It also improves by 10% over its predecessor on our Finance Agent Benchmark.
By contrast, it performs worse than Qwen 3 Max on both SWE-bench Verified and Terminal-Bench 2.0, placing 20th and 25th, respectively.
We also found that the model can get expensive on long-context agentic tasks, with the highest pricing tier equivalent to that of the Claude Sonnet models. Additionally, the model is worse than its predecessor at context caching, which increases prices per token further.
Congrats to the team at Alibaba on the release!
We’re releasing ProofBench, a new benchmark evaluating whether models can write formally verified mathematical proofs. Unlike natural language math benchmarks where subtle errors can go unnoticed, ProofBench requires proofs that are machine-checkable; either a solution compiles or it doesn’t.
- Aristotle, a system from Harmonic, achieved the best performance at 71%, roughly 2x the score of the best foundation model.
- Foundation models struggle significantly withs formal proof generation. Claude Opus 4.5 (Thinking) leads foundation models at 36%, followed by Gemini 3 Pro (11/25) at 20% and Claude Sonnet 4.5 (Thinking) at 19%.
- Problems are drawn from advanced undergraduate and graduate-level mathematics, spanning probability theory, measure theory, analysis, algebra, algebraic geometry, and number theory.
- While specialized tools like Aristotle show promise for assisting with formal mathematics, the large gap in foundation model performance highlights significant room for improvement in reliable formal reasoning.
We’ve finished our evaluation of Kimi K2.5 and continue to find excellent performance across the board. Here are some highlights:
- The model places first on CorpFin by a significant margin (2%), though it takes substantially longer to respond than other models in the top 10.
- The model is remarkably consistent - its worst placement is 16th, on CaseLaw, on which it remains within 10% of first place.
- The model is head and shoulders above its open-weight competition, placing first among open-weight models on 13 of the 17 benchmarks on which it was evaluated.
We ran all benchmarks on the native provider with temperature 1 as recommended by Kimi, with 128K max tokens on all but the coding benchmarks, for which we used 256K.
Stay tuned for our evaluation on Vibe Code Bench and congrats again to Moonshot on the release!
Kimi K2.5 is the new #1 open-weight model, taking the top spot on both our Vals Index and our Vals Multimodal Index. Here are the key takeaways:
- Like its predecessor Kimi K2 Thinking, the model excels across coding tasks, placing first across open-weight models on both SWE-bench Verified and Terminal-Bench 2.0.
- Unlike its predecessor, it also excels on our Finance Agent and SAGE, placing third across all models on the latter. By comparison, Kimi K2 Thinking didn’t even support multimodal input!
- Aside from being open-weight, another significant differentiation between Kimi and other top models is price - it’s the cheapest model in the top 10 of both Vals indices!
We ran all benchmarks on the native provider with temperature 1 as recommended by Kimi, with 128K max tokens on all but the coding benchmarks, for which we used 256K.
We’ve upgraded our Terminal-Bench evaluation to version 2. The new benchmark features more, better, and more relevant tasks.
Here are some key takeaways from our results:
- Claude Opus 4.5 (Nonthinking) leads the way on performance, scoring over 3% above its nearest competitor, Gemini 3 Pro (11/25). Surprisingly, its thinking variant Claude Opus 4.5 (Thinking), lags 4.5% behind in third place.
- We found that Gemini 3 Flash (12/25) demonstrates the most cost-effective performance, playing fourth at less than a fifth of the cost of the Claude models!
- GPT 5.2 and Grok 4 also demonstrate strong performance, as well as open-source offerings like MiniMax-M2.1 and GLM 4.7.
We’ve launched a new benchmark, Poker Agent, as a collaborative experiment with Graphite Digital. Poker Agent pits 17 models against each other in a head-to-head, ten-handed Poker competition.
- Unlike our other benchmarks, models compete directly against each other, and have to respond to each others actions.
- Models employed a variety of strategies. Some models like Grok 4.1 Fast (Reasoning) were very aggressive, others took a more conservative approach.
- GPT 5.2 was the top overall performer.
Allowing models to compete against each other in a shared, rather than isolated, environment represents an exciting new area of research. Stay tuned for more benchmark releases in 2026!
Evaluations are finished for MiniMax-M2.1.
- It does well among open-weight models on coding tasks, ranking among the top 5 performers in SWE-bench Verified, Terminal-Bench and Live Code Bench.
- It also ties for first place among open-weight models on our Case Law v2 benchmark, and is second among open-weight models on our Finance Agent benchmark.
- The model also offers these capabilities at a relatively low cost and latency compared with its peers.
While there remains significant room for improvement, it is a strong open-weight release from MiniMax AI, and we look forward to continued improvements on all our benchmarks.
NOTE: The model was tested with temperature=1 and top_p=0.95, via the Anthropic-compatible MiniMax API endpoint.
Evaluations are finished for GLM 4.7.
- It is neck and neck with DeepSeek V3.2 (Thinking) on SWE-bench Verified, 67.0% and 68.8% respectively. This is a +11% bump on SWE-bench Verified compared to GLM 4.6
- On Terminal-Bench, it was one of the top open-weight models, along with DeepSeek V3.2 (Nonthinking)
- Overall, it is more token efficient than its predecessor, and was much cheaper per-task, despite having the same input and output pricing.
The model was tested with temperature=1 and default top_p for all benchmarks but SWE-bench Verified and Terminal-Bench, which used temperature=0.7 and top_p=1. Reasoning was enabled for all benchmarks.
MiniMax-M2.1 ranks #2 among open-weight models on our Vals Index, but offers competitive performance with lower latency and cost compared to the #1 ranked open-weight model, GLM 4.7.
- It is #12 on the overall leaderboard, behind models from the likes of OpenAI, Gemini, and Anthropic.
- It ranks in the top 5 open-weight performers in all the benchmarks in our Vals Index.
The model was tested with temperature=1 and top_p=0.95, via the Anthropic-compatible MiniMax API endpoint.
Congratulations to MiniMax for a strong open-weight release! Results on the full suite of benchmarks will be released soon!
GLM 4.7 debuts at #1 on our open-weight leaderboard.
- It is #9 on the overall leaderboard, behind models from the likes of OpenAI, Gemini, and Anthropic. It is currently the only open-weight model in the top ten.
- It is a significant performance improvement over GLM 4.6, with a +9.5% performance increase.
- Despite being priced the same per-token, we also found that it was cheaper than GLM 4.6, using tokens more efficiently.
- The model uses a new interleaved thinking mode, which may explain the large bump in performance.
The model was tested with temperature=1 and default top_p for all benchmarks but coding benchmarks, which used temperature=0.7 and top_p=1. Reasoning was enabled for all benchmarks.
Results on full benchmarks will be released soon!
We’ve run all our benchmarks for Gemini 3 Flash (12/25) and found it continues to excel!
- Gemini 3 Flash (12/25) places first on SWE-bench Verified, with a score of 76.2%.
- Gemini 3 Flash (12/25) continues to perform comparably to Gemini 3 Pro (11/25) - see our comparison page
- Gemini 3 Flash (12/25) also places first on MMMU Pro, demonstrating strong visual understanding. It places second on IOI v1, SAGE, MMLU Pro, and LegalBench.
Congrats again to Google on the release!
We evaluated Gemini 3 Flash (12/25) and found strong performance at a small fraction of a cost of other frontier models like GPT 5.2 and Claude Opus 4.5 (Thinking).
While the model doesn’t achieve SOTA performance on any of our evaluations, it certainly comes close! It places second on SAGE , only 0.2% behind Claude Opus 4.5 (Thinking) for less than a tenth of the cost per token!
Incredibly, Gemini 3 Flash (12/25) outperforms Gemini 3 Pro (11/25) according to our comparison page
Congratulations to the Google team on another outstanding model!
We evaluated Mistral’s new Devstral 2 models (Devstral 2 and Devstral Small 2) on our coding benchmarks (IOI, LCB, SWE-bench Verified, and Terminal-Bench). Both models are open-source and designed for software engineering tasks.
-
Devstral 2 shows strong performance on coding benchmarks, ranking 2nd among open-weight models on Terminal-Bench (43.75%) and 5th among open-weight models on SWE-bench Verified (50.4%).
-
Devstral Small 2 provides a more cost-effective option, ranking 7th among open-weight models on both Terminal-Bench (40.0%) and SWE-bench Verified (42.4%).
-
However, both models struggle on IOI v1 and LCB, pointing to room for improvement on coding tasks.
DeepSeek V3.2 (Nonthinking) has just claimed first place on our Open-Weight Vals Index at a third of the price of leading competitors!
- Both DeepSeek V3.2 (Nonthinking) and DeepSeek V3.2 (Thinking) lead the way with competitive performance on SWE-bench Verified and our proprietary Finance Agent Benchmark.
- Surprisingly, we found that DeepSeek V3.2 (Nonthinking) generally outperformed DeepSeek V3.2 (Thinking) - see our comparison page for details
- Both models constitute a significant improvement over DeepSeek V3.1
That said, neither model is truly SOTA: the best placement either achieves is ninth on Terminal-Bench. With Christmas coming up, we look forward to further innovations from DeepSeek!
GPT 5.2 is the new state of the art on our Vals Index, showing strong performance across domains, especially coding.
Most impressive was the model setting a new state-of-the-art on Vibe Code Bench by an extremely large margin, from 24.6% to 41.31%. It also got first on our IOI v1, Terminal-Bench, and SWE-bench Verified.
This performance improvement does come with an increased cost across the board - the model is priced at $1.75 / $14, compared to $1.25 / $10 for its predecessor. It also tends to see increased token usage, especially on longer running agentic tasks. With the “high” or the new “xhigh” reasoning modes enabled, you may also see very long response times - for particularly tricky questions, it would think for more than 30 minutes.
Overall, the model will be a powerhouse for users seeking strong performance and reliability, particularly on complex reasoning and coding tasks.
We’ve evaluated GPT 5.1 Codex Max on our coding benchmarks. It boasts a +9.5% performance boost on VibeCodeBench (#3), +1% performance on SWE-bench Verified (#4), and a slight regression on Terminal-Bench.
This is not the fastest model in the shed. It’s 3x slower on SWE-bench Verified, 10x on VCB. This is a model for when you need the absolute best, not when you need it quickly.
Correlation isn’t causation… …but the more suffixes we tack onto these models, the longer they seem to take. Excited to test 5.25 Codex Max Ultra High Supreme Edition
The model was run with reasoning high and verbosity medium through OpenAI’s API. Results on IOI v1 and LCB will be released soon!
We found that Mistral Large 3 struggles across domains:
- We found a variety of difficulties with agentic use-cases involving tool-calling. We’re working with the Mistral team to address one such issue.
- The model places second-to-last on our Vals Multimodal Index, ahead of Llama 4 Maverick.
However, there are a few caveats:
- the model represents a meaningful improvement over predecessors like Magistral Medium 1.2 (09/2025) and Mistral Medium 3.1 (05/2025).
- The model is open-weight and performs comparably to other open-weight models like GPT OSS 120B.
We look forward to further improvements from Mistral to come!
Mistral Large 3 is #20 on our Vals Index (out of 24).
A main source of failure was the model’s difficulty in calling tools - a common error mode was the model making a function call with a malformed tool name (e.g. inserting the function arguments into the tool name). (2/3)
However, it achieves a six percentage point increase over Magistral Medium 1.2 (09/2025), with comparable performance on the Vals Index to GPT OSS 120B.
Full results will be posted soon.
Claude Opus 4.5 (Thinking) is the new leader on our Vals Index, surpassing its cheaper variant, Claude Sonnet 4.5 (Thinking).
Like other Anthropic models, Claude Opus 4.5 (Thinking) demonstrates strong performance on coding tasks - the thinking and nonthinking variants take the top 2 spots on SWE-bench Verified. However, the model performs worse than Claude Sonnet 4.5 (Thinking) on our new VibeCodeBench.
Unlike other Anthropic models, Claude Opus 4.5 (Thinking) showcases strong multimodal capabilities, placing first on our Multimodal Vals Index. It also places first on SAGE, surpassing the previous leader, Gemini 3 Pro (11/25). It’s also cheaper than before - it’s a third of the price of Claude Opus 4.1 (Nonthinking) and on some benchmarks, more token efficient than Claude Sonnet 4.5 (Thinking)!
Along with Claude Sonnet 4.5 (Thinking) and Claude Opus 4.5 (Thinking), the top 3 models on our Vals Index are now all from Anthropic. We look forward to other providers catching up!
We just released Vibe Code Bench : the first benchmark that tests whether AI models can actually build complete web applications from scratch.
- GPT 5.1 takes first place with 24% accuracy, improving by 4% over its third-place predecessor GPT 5 (with 20% accuracy).
- Claude Sonnet 4.5 (Thinking) takes second place, but costs more than twice as much than the OpenAI models.
- Despite the much-vaunted release, Gemini 3 Pro (11/25) lags behind in fourth place, with only 14.3% accuracy.
Overall, we see these results as evidence that vibe code has plenty of room to improve. We look forward to seeing this improvement!
We just evaluated Grok 4.1 Fast (Reasoning) and Grok 4.1 Fast Non-Reasoning on all benchmarks!
We found that the reasoning variant consistently outperforms the non-reasoning variant - see our comparison page. Grok 4.1 Fast Non-Reasoning struggles - its best performance is tenth place on our IOI v1 benchmark, while Grok 4.1 Fast (Reasoning) achieves strong performance across the board, placing third on our CorpFin benchmark.
Both models perform similarly to their predecessors - see our comparison pages for both the reasoning and non-reasoning variants. Like their predecessors, both models are also extremely cost-efficient on a per-token basis.
Congratulations to the SpaceXAI team for the launch of Grok 4.1!
We just evaluated Gemini 3 Pro (11/25) on our Vals Index! Key takeaways:
Gemini 3 Pro (11/25) demonstrates strong performance across the board, placing first on SAGE, GPQA Diamond and MortgageTax and second on our Multimodal Vals Index.
Gemini 3 Pro (11/25) is three times faster than GPT 5.1, and is also cheaper than Claude Sonnet 4.5 (Thinking), the leader on the Vals Multimodal Index.
Overall, Gemini 3 Pro (11/25) excels in multimodal use cases and provides meaningful improvement over its predecessor, Gemini 2.5 Pro Exp.
We just evaluated GPT 5.1 on all benchmarks. Our findings are below:
- GPT 5.1 takes second place on the Vals Index, behind the reigning champion, Claude Sonnet 4.5 (Thinking).
- GPT 5.1 shines on agent benchmarks, placing first on our Finance Agent Benchmark.
- GPT 5.1 also excels at competitive coding, placing second on both LiveCodeBench and our IOI v1 Benchmark.
- GPT 5.1 performs comparably to GPT 5, but much more cheaply and quickly - we consider it a clear leader on Pareto frontier between performance and cost.
We evaluated Kimi K2 Thinking on all benchmarks, finding strong performance on coding benchmarks like SWE-bench Verified. We otherwise found middle-of-the-pack performance on both public and private benchmarks.
In comparison to Kimi K2 Instruct, we found a modest improvement across most industries, with the exception of legal and finance. For instance, the Instruct model outperforms the thinking model by nearly 5% on our TaxEval benchmark.
Overall, we found Kimi K2 Thinking to be a strong successor to Kimi K2 Instruct, but doesn’t live up to the twitter hype of “best model on the market”.
We just evaluated Kimi K2 Thinking on our Vals Index! We found it to improve upon the already solid performance of Kimi K2 Instruct, placing 2nd in our open-weight category.
Kimi K2 Thinking especially shines on agentic use-cases requiring iterative tool calling, like our Finance Agent Benchmark. It performs similarly to Kimi K2 Instruct on other benchmarks.
One meaningful downside of the model is its latency - on average, Kimi K2 Thinking takes almost five times as long as GLM 4.6, the leader on our open-weight Vals Index.
Overall, we see Kimi K2 Thinking as an important contribution to the open-source ecosystem.
We’re excited to introduce the Multimodal (image-based) variant of our Vals Index ! It extends upon the original Vals Index with two of our private multimodal benchmarks:
- MortgageTax, which tests models’ ability to read and understand tax certificates
- SAGE, which tests models’ ability to grade handwritten undergraduate student work
As with our Vals Index, Claude Sonnet 4.5 (Thinking) tops the Vals Multimodal Index leaderboard, followed closely by GPT 5 and Claude Haiku 4.5 (Thinking). Price-conscious consumers might turn to Haiku or GPT 5 Mini, while Gemini 2.5 Pro and Grok 4 lag behind.
For our initial release, we only include closed-source models from 4 major providers: OpenAI, Anthropic, Google, and SpaceXAI. In the future, we hope to add open-source multimodal models like Qwen 3 VL Plus.
We evaluated GLM 4.6 on all benchmarks and found it improves upon the already strong performance of GLM 4.5, leading the [open-source category of our Vals Index.
- While GLM 4.6 outperforms its predecessor GLM 4.5, it underperforms compared to Qwen 3 Max
- GLM 4.6 excels at coding, placing in the top 10 on both SWE-bench Verified, Terminal-Bench, and LiveCodeBench. This reproduces z.AI internal results on the latter two benchmarks, though lags 10 points behind internal numbers on SWE-bench Verified.
- GLM 4.6 struggles on our private benchmarks, underperforming compared to GLM 4.5 on our Finance Industry Leaderboard.
See our comparison with GLM 4.5 for more context.
We evaluated Claude Haiku 4.5 (Thinking) and found strong performance:
- The model places 3rd on our Vals Index, demonstrating well-rounded capabilities across diverse tasks.
- On Terminal-Bench, Haiku 4.5 achieves 3rd place, showing particular strength on coding tasks.
- While it performs well on certain coding benchmarks, the model achieves middle-of-the-pack performance on most other benchmarks.
- The model struggles significantly on our proprietary CaseLaw benchmark and the public MedQA, GPQA Diamond, MMLU Pro, MMMU Pro, and LiveCodeBench benchmarks.
- Compared to Claude Sonnet 4.5 (Thinking), Haiku trades some performance for significantly faster speed and lower cost - see our model comparison for details.
Overall, Haiku 4.5 sits firmly on the Pareto frontier.
Our new Student Assessment with Generative Evaluation (SAGE) benchmark evaluates the ability of Language Models to grade handwritten student work at the undergraduate level.
- No models score higher than 50%; by contrast, top models consistently achieve >90% accuracy on mathematical benchmarks like AIME.
- Gemini 2.5 Flash (7/17) (Nonthinking) takes first place with 44.8% - outperforming Gemini 2.5 Pro by 3%!
- Current results show significant variation in performance by model provider, with less variation in particular model. With the exception of the two smallest models we tested (Gemini 2.5 Flash Lite (Nonthinking) and GPT 5 Nano), all OpenAI and Google models do better than all Anthropic models, which in turn do better than Grok 4.
We find significant room for improvement in models’ capabilities here, and are excited for the SAGE benchmark to enable continued model development for education!
We evaluated Magistral Medium 1.2 (09/2025) and Magistral Small 1.2 (09/2025) - and found that both models perform decently for their size, especially on coding tasks. However, the models also struggled on many benchmarks.
- Magistral Medium performs well on academic and coding benchmarks, placing in the top 20 on LiveCodeBench and AIME. However, the model struggles on our proprietary benchmarks, particularly MortgageTax and CaseLaw.
- Surprisingly, Magistral Small tends to do better on finance and academic benchmarks, most notably outperforming Medium on MortgageTax (+8.8%). The model also does well on LiveCodeBench and AIME. However, Small struggled on our proprietary CorpFin and CaseLaw benchmarks, along with GPQA Diamond and MMLU Pro.
- A large chunk of the performance loss was the result of models not outputting results in the format that was required.
The Medium model is priced at $2 / $5, and the Small at $0.5 / $1.5. The Small model has open weights, whereas the Medium model is only available via API.
We ran the recently-released Claude Sonnet 4.5 (Thinking) our benchmarks, and found very strong performance:
- On Finance Agent, it beats the previous state-of-the-art by five percentage points.
- It also takes the #1 spot on SWE-bench Verified and Terminal-Bench, beating out GPT 5 Codex.
- It is in the top 10 models on the majority of our benchmarks, and also showed better performance than Claude Sonnet 4 (Thinking) on almost all benchmarks.
- It has a 1-million token context window, when the flag “context-1m-2025-08-07” is enabled
Overall, this model is extremely capable, at the same mid-range price point as its predecessor.
We evaluated Gemini 2.5 Flash Preview (9/25) (Thinking) (and also the Flash Lite model) and found the following:
-
Compared to the previous version, the update shows improvements on GPQA Diamond, with a ~17% increase over the previous version.
-
Flash improved on Terminal-Bench (+5%), GPQA Diamond (+17.2%), and our private Corp Fin Benchmark (+4.4%). It also ranks #3/38 on MMMU Pro and #6/20 on SWE-bench Verified (for the thinking model), while delivering performance at half the cost of similar models.
-
Flash Lite matches Flash on several public benchmarks, making it a very cost-effective option. However, Flash outperforms Lite by ~10% on our private benchmarks (CaseLaw v2, TaxEval, Mortgage Tax).
-
Flash delivers competitive performance at a fraction of the cost of other foundation models.
Overall, the latest update to Gemini 2.5 Flash is a highly efficient model that balances strong performance with low cost.
We evaluated Qwen 3 Max and found the following:
-
Qwen 3 Max breaks the top 20 on 5 benchmarks, with leading open source scores on LiveCodeBench, MMLU Pro, and GPQA Diamond.
-
Overall scores are similar to Qwen 3 Max Preview, with gains on just three benchmarks: FAB (+15%), IOI v1 (+8%), and AIME (+17.2%). However, Qwen 3 Max Preview far outperformed Max on LegalBench (78.9% vs. 38.1%).
-
Our results were lower than Alibaba’s reported AIME25 score by 11.6%, though LiveCodeBench results aligned closely.
Overall, Qwen 3 Max is a solid, middle-of-the-pack model. It shows incremental gains over Qwen 3 Max Preview on FAB, IOI v1, and AIME, while underperforming on LegalBench.
We evaluated GPT 5 Codex across Terminal-Bench, SWE-bench Verified, IOI v1, and LCB, finding the following:
- On Terminal-Bench, GPT-5 Codex takes 1st place with 58.8% accuracy, a 10% improvement over the previous #1, GPT-5. It also delivers lower cost and latency compared to the other top three models.
- GPT 5 Codex also gets first place on SWE-bench Verified, narrowly outperforming GPT 5, which ranks 2nd by less than a percentage point.
- GPT 5 Codex is the first model we’ve seen receive full credit on a single question on IOI v1, though overall accuracy remains low (9.8%).
- GPT 5 Codex places second on LCB, behind GPT 5 Mini.
GPT 5 Codex is optimized for agentic coding, particularly within OpenAI’s Codex offering. For standardization, we used the same prompts and templates as we used with other models when running our evaluations.
We evaluated Grok 4 Fast (Reasoning) and Grok 4 Fast (Non-Reasoning), and found the following:
- Grok 4 Fast (Reasoning) delivers impressive latency and pricing, comparable to GPT-5 Nano. For example, on Corp Fin, it was half the latency and 10% of the cost compared to Grok 4.
- The Reasoning model significantly outperforms the Non-Reasoning variant. While Grok 4 Fast (Non-Reasoning) did not place in the top 10 on any benchmark, Grok Fast (Reasoning) achieved #3 on both AIME and CorpFin.
- The results highlight the growing performance gap between reasoning and non-reasoning models, particularly on complex benchmarks.
Overall, this is a very performant model from the SpaceXAI team for its price and latency.
We evaluated the top foundation AI models on Terminal-Bench, and found GPT 5 claimed the #1 spot, scoring 48.8% across all 80 tasks.
Terminal-Bench tests AI agents’ ability to perform real-world tasks using only the terminal.
-
Overall, models struggle on this benchmark. Even the latest flagship models fail to break 50% average accuracy overall.
-
Additionally, we found that performance drops sharply as tasks get harder: average accuracy falls from 63% on easy tasks to 16% on hard tasks.
-
Common failure modes we observed included models not waiting for a process to finish before sending the next command, missing edge cases, and crashing the terminal entirely.
Latency across the board was also high - with models taking up to a few minutes at the low end, and up to three minutes at the highest end.
We evaluated Qwen 3 Max Preview on our benchmarks. Despite the model’s large size, we found the performance did not live up to the hype.
-
On our benchmarks, it was generally in the middle of the pack - but not in the top 5 on any benchmarks, and on most, it was outside the top 20. On Finance Agent, it only managed to get 17% accuracy.
-
Qwen 3 Max Preview did have comparatively strong performance on MGSM and GPQA Diamond, but these benchmarks are saturated, and incremental gains here do not signify meaningful differences in model intelligence.
-
This model is not open source, which is one of the main benefits of the Qwen series. It is also more expensive than its open source counterpart, Qwen 3 (235B), but often performs worse.
Alibaba has currently only released the non-reasoning version of max preview. We’re excited to benchmark the reasoning version when it’s available, which may improve responses on benchmarks like AIME.
We evaluated Z.ai’s GLM 4.5 model and found the following:
- GLM 4.5 delivers solid top-twenty results on AIME (#5/51), GPQA Diamond (#16/53), MMLU Pro (#15/51), LiveCodeBench (#15/53), and our own CaseLaw benchmark (#20/27).
- When compared directly to U.S. open-source peers, GLM 4.5 performs better than models such as Llama 4 Maverick, but is still outperformed by GPT OSS 120B across nearly every benchmark.
GLM 4.5 definitely still has room for improvement. We’re looking forward to seeing how open-source models continue to progress, but for now there is still a long way to go.
We evaluated SpaceXAI’s Grok Code Fast on three of our coding benchmarks and found it to be much faster (and cheaper) for practical coding tasks, but significantly worse than SpaceXAI’s flagship model Grok 4 in general. Our findings are below:
- Grok Code Fast scores 62% on LCB, placing the model in the middle of the pack, comparable to other reasoning models like Claude Sonnet 4 (Nonthinking), but for a tenth of the price.
- On IOI v1, Grok Code Fast gets 4.3% placing the model at 8/12. By contrast, Grok 4 gets 26.2% and places first overall!
- On SWE-bench Verified, Grok Code Fast gets an impressive 57.6% percent, placing 4th right behind Grok 4‘s 58.6%, but with a latency of 264.68s compared to Grok 4‘s 704.8s.
Grok Code Fast is a snappier (and cheaper) model optimized for coding, and our results show that while there is significant room for improvement relative to other frontier models including SpaceXAI’s Grok 4, it performs competitively on practical coding tasks while offering benefits in terms of latency and cost.
GPT 5 achieved the highest overall accuracy on SWE-bench Verified, attaining an impressive 68.8%!
Results released come from running the model with the following settings:
- High reasoning
- Default verbosity
- New response endpoint
Evaluated across all four task categories based off difficulty and 500 benchmark instances, GPT 5 ranked first in every category except for the “>4 hours” group, where it was among four models tied with a 33% completion rate on the most challenging tasks.
These results demonstrate that GPT 5 represents a significant advancement over previous OpenAI models.
Our CaseLaw benchmark studies how well language models are able to perform case law reasoning and legal document analysis. We refreshed the benchmark to include harder and up-to-date questions, since the first version of our benchmark was getting saturated.
From our evaluations, we found:
- GPT 4.1 maintained the top performance with 78.1% accuracy.
- GPT 5 Mini emerged as a strong second-place performer, and had faster processing times; Grok 4 ranked third on the benchmark.
- A common failure mode was identifying only parts of relevant document sections, relying more on their general knowledge despite being instructed otherwise.
While top models performed well, many still struggled with the nuanced interpretation required for legal analysis. CaseLaw v2 highlights both current strengths and the work ahead for applying AI in legal workflows.
Recently, top LLM labs like OpenAI and Google reported that their models achieved gold medals on the International Mathematical Olympiad (IMO). This suggests that advanced models are saturating IMO, so we decided to test models on the International Olympiad in Informatics (IOI)! The results below are the original harness, now archived as IOI v1.
From our evaluations, we found:
- Grok 4 wins convincingly, placing first on both the 2024 and 2025 exams.
- Models struggle to write C++ at the level of the best high-school students – no models qualify for medals on either exam.
- Only the largest and most expensive models even come close to placing. The only models to achieve >10% performance all cost at least $2 per question. Claude Opus 4.1 (Nonthinking) costs over $10 per question!
- Consistency between performance on the 2024 and 2025 tests suggests that LLM labs aren’t currently training on the IOI, suggesting that this benchmark is relatively free from data contamination.
We just evaluated Claude Opus 4.1 (Thinking) on our non-agentic benchmarks. While it placed in the top 10 on 6 of our public benchmarks, its performance on our private benchmarks was fairly mediocre.
-
On our private benchmarks, Claude Opus 4.1 (Thinking) lands squarely in the middle of the pack — barely making the top 10 on our TaxEval benchmark.
-
On public benchmarks, however, Claude Opus 4.1 (Thinking) ranks in the top 10 on 6 of the benchmarks we evaluated. Notably, it takes 2nd place on MMLU Pro behind only Claude Opus 4.1 (Nonthinking) and claims 1st place on MGSM.
We just released results on Claude Opus 4.1 (Nonthinking) and found that, despite achieving top spots on MMLU Pro and MGSM, the model performs only marginally better across almost all of our benchmarks (<2% performance gain) compared to Claude Opus 4 (Nonthinking).
On our private benchmarks, Opus 4.1 fails to place among the top 10 models. On public benchmarks, however, the model breaks the top 10 on 5 of the 9 public benchmarks we evaluated. This signals the need for more private benchmarks to evaluate meaningful differences between models and gauge true performance.
We evaluated OpenAI’s newly-released GPT 5 family of models and found that GPT 5 achieves SOTA performance for a fraction of the cost compared to similarly performing models.
Of the three, GPT 5 is the strongest model in the family with SOTA performance on public LegalBench and AIME benchmarks.
On private benchmarks, GPT 5 and GPT 5 Mini achieve top 10 performance on all but CaseLaw. Most notably, GPT 5 Mini is the new SOTA model on TaxEval at a substantially lower cost.
On public benchmarks, GPT 5 places top 5 and GPT 5 Mini places top 10 on nearly everything. Further, we found the two models have complementary strengths - GPT 5 is SOTA on LegalBench and AIME, while GPT 5 Mini is SOTA on LiveCodeBench.
Lastly, GPT 5 Nano achieves middle of the pack performance across the board. It narrowly places in the top 10 on AIME, compared to GPT 5 and GPT 5 Mini which top the charts.
Our SWE-bench Verified evaluation of Kimi K2 Instruct achieved 34% accuracy, barely more than half of Kimi’s published figures!
After investigating the model responses, we identified the two following sources of error:
- The model struggles to use tools - it often includes tool calls in the response itself! We replicated the issue on multiple popular inference providers. However, even discarding such errors only increases accuracy by around 2%.
- The model often gets stuck repeating itself, leading to unnecessarily long and incorrect responses. This is a common failure mode of models at zero temperature, though it’s most prevalent among thinking models.
We evaluated Llama 3.3 Nemotron Super (Nonthinking) and Llama 3.3 Nemotron Super (Thinking) and found the Thinking variant substantially outperforms the Nonthinking variant, with the significant exception of our proprietary Contract Law benchmark.
-
On Contract Law, Llama 3.3 Nemotron Super (Thinking) struggles, ranking in the bottom 10 models. Meanwhile, Llama 3.3 Nemotron Super (Nonthinking) lands in the top 3!
-
On TaxEval and CaseLaw, Llama 3.3 Nemotron Super (Nonthinking) (Non-thinking) struggles significantly, while Llama 3.3 Nemotron Super (Thinking) sits solidly middle-of-the-pack.
-
On public benchmarks, Llama 3.3 Nemotron Super (Nonthinking) performs abysmally across the board. Llama 3.3 Nemotron Super (Thinking) improves on all public benchmarks but still struggles, particularly on MGSM (35/46) and MMLU Pro (31/43).
-
Llama 3.3 Nemotron Super (Thinking) shows substantial gains over Llama 3.3 Nemotron Super (Nonthinking): on AIME, performance improves from 37/44 to 14/44, and on Case Law, accuracy increases by 12%. These results highlight the benefits of the reasoning model.
We found that Kimi K2 Instruct is the new state-of-the-art open-source model according to our evaluations.
The model cracks the top 10 on Math500 and LiveCodeBench, narrowly beating out DeepSeek R1 on both. On other public benchmarks, however, Kimi K2 Instruct delivers middle-of-the-pack performance.
However, Kimi K2 Instruct struggles on our proprietary benchmarks, failing to break the top 10 on any of them. We noticed it particularly struggles with legal tasks such as Case Law and Contract Law but performs comparatively better on finance tasks such as Corp Fin and Tax Eval.
The model offers solid value at $1.00 input/$3.00 output per million tokens, which is cheaper than DeepSeek R1 ($3.00/$7.00, both as hosted on Together AI) but more expensive than Mistral Medium 3.1 (05/2025) ($0.40/$2.00).
We’re currently evaluating the model on SWE-bench Verified, on which Kimi’s reported accuracy would top our leaderboard. Looking forward to seeing whether the model can live up to the hype!
We evaluated Grok 4 on the Finance Agent, CorpFin, SWE-bench Verified, and LegalBench benchmarks and found strong results, especially on our private benchmarks.
-
On CorpFin, the model achieves state-of-the-art performance by a significant margin, placing first by the largest margin of any other model in the top 10!
-
Grok 4 ranks in the top 10 for model performance on the Finance Agent benchmark.
-
On LegalBench, Grok 4 places second behind Gemini 2.5 Pro Preview, illustrating potential saturation on this public, legal benchmark.
-
On SWE-bench Verified, Grok 4 scores place second only to Claude Sonnet 4 (Nonthinking) and show a 15% improvement over previous Grok 4 results. Though Grok 4 uses tools 50% less often than Claude Sonnet 4 (Nonthinking), this does not yield an improvement in overall price.
In the livestream, Elon Musk called Grok 4 “partially blind”. We tested this claim on our two multimodal benchmarks (Mortgage Tax and MMMU Pro) and found a bigger gap between public and private benchmarks. We found that Grok 4 struggles to recognize unseen images, highlighting the importance of high-quality private datasets to evaluate image recognition capabilities.
As we continue to evaluate Grok 4 on our benchmarks, the model continues to struggle on our private ones. The middling performance on Tax Eval (67.6%) and Mortgage Tax (57.5%) is consistent with previous findings on our private legal tasks like Case Law and Contract Law.
On public benchmarks, Grok 4 achieves top-10 performance on both MMLU Pro (85.3%) and MMMU Pro (76.5%).
We found that Grok 4 struggles on our private benchmarks, in contrast to SOTA performance on AIME, Math 500, and GPQA Diamond.
Grok 4 delivers middle-of-the-pack performance on our private legal benchmarks. The model scores 80.6% on Case Law and 66.0% on Contract Law, underperforming Grok 3 Mini Reasoning on both and Grok 3 on Case Law. Notably, Grok 3 remains our top performer on the Case Law benchmark.
On public benchmarks, Grok 4 barely cracks the top 10 on MedQA at 92.5%, narrowly outperforming Grok 2. On MGSM, it fails to break the top 10 with 90.9%. This contrasts its SOTA performance on Math 500, suggesting Grok 4 struggles more with language than mathematical reasoning.
We received early access to SpaceXAI’s latest Grok 4 and an initial set of smaller benchmarks. These early results show incredible performance — the model sets the new state-of-the-art on AIME, GPQA Diamond, and Math 500 benchmarks! Grok 4 is extremely capable in its ability to answer challenging math and science questions.
We are continuing to run our evaluations on our private benchmarks and will release results shortly.
-
Foundation models still fail to solve real-world coding problems despite notable progress, highlighting remaining room for improvement.
-
The models’ performance drops significantly on “harder” problems that take >1 hour to complete. Only Claude Sonnet 4 (Nonthinking), o3 and GPT 4.1 pass any of the >4 hour tasks (33% each).
-
Claude Sonnet 4 (Nonthinking) leads by a wide margin with 65.0% accuracy, and maintains both excellent cost efficiency at $1.24 per test and fast completion times (426.52s).
-
Tool usage patterns reveal models employ distinct strategies. o4 Mini brute-forces problems (~25k searches per task), while Claude Sonnet 4 (Nonthinking) employs a leaner, balanced mix (~9-10k default tool calls with far fewer searches).
Note that we run every model through the same evaluation harness to make direct comparisons between models, so the scores show relative performance, not each model’s best possible accuracy.
We’ve released our evaluation of Claude Opus 4 (Nonthinking) across our benchmarks!
We found:
- Opus 4 ranks #1 on both MMLU Pro and MGSM, narrowly setting new state-of-the-art scores. However, it achieves middle of the road performance across most other benchmarks.
- Compared to its predecessor (Opus 3), Opus 4 ranked higher on CaseLaw (#22 vs. #24/62) and LegalBench (#8 vs #32/67) but scored notably lower on ContractLaw (#16 vs. #2/69)
- Opus 4 is expensive, with an output cost of $75.00 /M tokens, 5x as much as Sonnet 4, and about 1.5x more expensive than o3 ($15 / $75 vs $10 / $40).
We also benchmarked Claude Sonnet 4 (Thinking) and Claude Sonnet 4 (Nonthinking) on our Finance Agent benchmark (the last remaining benchmark for this model). They performed nearly identically to Claude 3.7 Sonnet (Nonthinking).
We’ve released our evaluation of Claude Sonnet 4 (Thinking) across all of our benchmarks!
- Claude Sonnet 4 (Thinking) seriously underperforms when compared to its predecessor Claude 3.7 Sonnet (Thinking) on our proprietary TaxEval and ContractLaw benchmarks.
- Claude Sonnet 4 (Thinking) significantly outperformed Claude Sonnet 4 (Nonthinking) on our reasoning benchmarks. For example, Claude Sonnet 4 (Thinking) scored 76.3% and Claude Sonnet 4 (Nonthinking) scored 38.5% on our AIME benchmark.
- Claude Sonnet 4 (Thinking) is consistently in the top 10 across most of our benchmarks, though it is never the SOTA model.
- The model latency is high when reasoning is enabled with a high token budget. On AIME, the model responded in four minutes, on average, with some questions taking over ten minutes.
The full writeups are linked in the comments. The final determinant of the Claude 4 family strengths will come from Opus 4, so stay tuned for the results!
We just evaluated Claude Sonnet 4 (Nonthinking) on all benchmarks!
- Claude Sonnet 4 (Nonthinking) achieves 76.9% accuracy on average, a 7.1% improvement on Anthropic’s previous flagship model, Claude 3.7 Sonnet. The newer Claude is also nearly twice as fast for the same price.
- Claude Sonnet 4 (Nonthinking) excels on the MGSM benchmark, edging out Claude 3.7 Sonnet (Thinking) by a tenth of a percentage point.
- Claude Sonnet 4 (Nonthinking) also achieves strong performance on our proprietary CaseLaw benchmark, outperforming all previous Anthropic models.
- Interestingly, Claude Sonnet 4 (Nonthinking) performs worse than its predecessor Claude 3.7 Sonnet by six percentage points on the MortgageTax benchmark. It even performs worse than its predecessor, Claude 3.5 Sonnet, on both the MortgageTax and CorpFin benchmarks!
Stay tuned for evaluations of Sonnet 4’s thinking variant, as well as Opus 4!
We just evaluated Mistral Medium 3 on all benchmarks!
-
Mistral Medium 3 demonstrates consistent performance across both public and proprietary benchmarks, scoring 68.7% overall accuracy with strong results on CaseLaw (84.9%, #6/59) and Math500 (87.0%, #17/42) given its size and price.
-
The model outperforms Llama 4 Maverick (63.3% accuracy) in most benchmarks, particularly excelling in MGSM (91.6% vs 92.5%) and MMLU Pro (74.4% vs 79.4%).
-
While impressive, Mistral Medium 3 still trails behind Qwen 3 235B (81.0% accuracy) on several academic benchmarks, particularly Math500 (87.0% vs 94.6%) and AIME (42.3% vs 84.0%).
-
For users seeking speed-performance balance, Mistral Medium 3 offers good latency (14.37s) compared to Qwen 3 235B (94.31s), making it suitable for applications requiring faster response times while maintaining strong reasoning capabilities.
We just evaluated Gemini 2.5 Flash Preview (Nonthinking) on most benchmarks.
- Gemini 2.5 Flash Preview (Nonthinking) is a lightweight alternative to Google’s flagship model, Gemini 2.5 Pro Exp. Gemini 2.5 Flash Preview (Nonthinking) runs at a fraction of the cost and latency, rendering it a more accessible option.
- Like Claude 3.7 Sonnet (Nonthinking), Gemini 2.5 Flash Preview (Nonthinking) is a hybrid reasoning model, meaning it can adaptively choose how much to think before responding.
- Gemini 2.5 Flash Preview (Nonthinking) excels on LegalBench, coming second only to the flagship Gemini 2.5 Pro Exp (and outperforming its own thinking variant, Gemini 2.5 Flash Preview (Thinking), by 1%).
- We consistently had difficulty with Google’s API during evaluation, which prevented us from reporting full results. We’re working with a representative from the Gemini team to resolve those issues.
We just evaluated Qwen 3 235B on all benchmarks!
-
Qwen 3 235B demonstrates exceptional math reasoning capabilities, ranking #3 on Math500, #5 on AIME, and #3 on MGSM.
-
With its “thinking allowed” approach, Qwen 3 outperforms several prominent closed-source reasoning models including Claude 3.7 Sonnet and o4-mini in mathematical reasoning tasks.
-
Private benchmark challenges: Qwen 3 shows limitations on proprietary benchmarks, particularly struggling on TaxEval where it ranks #29 out of 43 evaluated models.
-
This evaluation showcases Qwen 3’s strong specialized reasoning capabilities while highlighting areas where further improvements could enhance its performance on domain-specific tasks.
- Our new Finance Agent Benchmark evaluates AI agents’ ability to perform tasks expected of entry-level financial analysts.
- Developed in collaboration with industry experts, it includes 537 questions covering skills like simple retrieval, market research, and projections.
- The models are expected to use a set of 4 tools to search through the web or the EDGAR database and parse the results to answer the questions.
- Current AI models do not exceed 50% accuracy, highlighting the need for further development before reliable deployment in the finance industry.
- At the time of this benchmark’s release, o3 is the best performing model reaching 48.3%, but at the cost of an average of $3.69 per question.
- It is followed closely by Claude Sonnet 3.7 Thinking which gets 44.1% accuracy, at the much lower price per question of $1.05.
We just evaluated o3 and o4 Mini on all benchmarks!
-
o3 achieved the #1 overall accuracy ranking on our benchmarks, with exceptional performance on complex reasoning tests like MMMU Pro (#1/22), MMLU Pro (#1/35), GPQA Diamond (#1/35) and proprietary benchmarks like TaxEval (#1/42) and CorpFin (#2/35).
-
o4 Mini achieved the second-highest accuracy across our benchmarks (82.8%), driven by strong performance on public math tests like MGSM (#1/36), MMMU Pro (#2/22), and Math500 (#4/38).
-
Legal benchmark weaknesses: Both models demonstrated significant weaknesses on our proprietary legal benchmarks, with lower ranks on ContractLaw (o3: #34/62, o4 Mini: #14/62) and CaseLaw (o3: #15/55, o4 Mini: #18/55).
-
Cost-effectiveness comparison: With similar performance levels, cost becomes a key differentiator. o4 Mini costs $4.40 for output, compared to $40.00 for o3 — a tenfold price difference that makes o4 Mini the more economical choice for many use cases.
We just evaluated GPT 4.1, GPT 4.1 Mini, and GPT 4.1 Nano on all benchmarks!
-
GPT 4.1 delivers impressive results with a 75.5% average accuracy across benchmarks.
-
Impressive performance on proprietary benchmarks! GPT 4.1 is now the leader on CorpFin (71.2%), and shows strong performance on CaseLaw (85.8%, 4/53), and MMLU Pro (80.5%, 6/33).
-
GPT 4.1 Nano and GPT 4.1 Mini bring AI to time-sensitive applications with an outstanding latency of only 3.62s and 6.60s respectively while still achieving 59.1% and 75.1% average accuracy.
-
Compact but capable! Despite its size, GPT 4.1 Mini performs admirably on Math500 (88.8%, 10/36) and MGSM (87.9%, 20/34).
-
Size versus performance tradeoff: The smaller models do show lower performance on some complex tasks, with GPT 4.1 Nano ranking near the bottom on MMLU Pro (62.3%, 30/33) and MGSM (69.8%, 32/34).
We just evaluated Grok 3 Beta, Grok 3 Mini Fast Beta (High Reasoning), and Grok 3 Mini Fast Beta (Low Reasoning) on all benchmarks!
-
Grok 3 Beta delivers impressive results with a 78.1% average accuracy across benchmarks and a snappy 15.52s latency.
-
Dominates proprietary benchmarks! Grok 3 Beta ranks #1 on three key benchmarks: CorpFin (69.1%), CaseLaw (88.1%), and TaxEval (78.8%).
-
Grok 3 Mini Fast Beta (High Reasoning) surprises with an even higher average accuracy of 81.6% despite being a smaller model.
-
Mathematical prowess! Grok 3 Mini Fast Beta (High Reasoning) takes the #2 place (94.2%) on Math500 and the #3 place (85.00%) on AIME.
We just evaluated Llama 4 Maverick and Llama 4 Scout on all benchmarks!
- Llama 4 Scout achieves an average accuracy of 61.5% with a latency of 7.13 seconds, placing the model at a tie with Mistral Small 3.1 (03/2025) (61.5%) and just behind Cohere’s Command A (63.5%).
- Llama 4 Maverick sits at 67.0% accuracy with a latency of 7.72 seconds ranking just behind Anthropic’s Claude 3.5 Sonnet (69.9%) and DeepSeek V3 (03/24/2025) (74.7%).
- Both models excel on public benchmarks, with Maverick achieving top rankings in MMMU Pro (4/17), MGSM (4/28), GPQA Diamond (5/27), and MMLU Pro (5/27), while Scout delivers strong results in MMMU Pro (10/17), MortgageTax (10/18), and AIME (11/26).
- However, these models show a significant gap between their impressive public benchmark performance and mediocre results on private benchmarks, particularly struggling with TaxEval (Maverick: 28/34, Scout: 32/34), Contract Law (Maverick: 37/54, Scout: 43/54), and MedQA (Maverick: 32/32, Scout: 30/32).
We just evaluated Mistral Small 2503 on all benchmarks!
- Mistral Small 3.1 is Mistral AI’s latest small model, achieving an average accuracy of 61.4% across all benchmarks with a latency of 6.52s - faster than GPT-4o Mini (9.89s) and Llama 3.3 70B (7.67s).
- Despite its compact size, Mistral Small outperforms Claude 3.5 Haiku (60.2%) in overall accuracy while offering competitive performance to GPT-4o Mini (62.8%).
- The model excels on MGSM with 85.4% accuracy, comparable to Claude Haiku (85.9%) but behind Llama 3.3 70B’s impressive 91.3%.
- Like Claude Haiku, the model struggles with AIME (both 3.5%), well behind GPT-4o Mini (11.5%) and Llama 3.3 70B (16.6%).
We just evaluated Gemini 2.5 Pro Exp on all benchmarks!
- Gemini 2.5 Pro Exp is Google’s latest experimental model and the new State-of-the-Art, achieving an impressive average accuracy of 82.3% across all benchmarks with a latency of 24.68s.
- The model ranks #1 on many of our benchmarks including CorpFin, Math500, LegalBench, GPQA Diamond, MMLU Pro, and MMMU Pro.
- It excels in academic benchmarks, with standout performances on Math500 (95.2%), MedQA (93.0%), and MGSM (92.2%).
- Gemini 2.5 Pro Exp demonstrates strong legal reasoning capabilities with 86.1% accuracy on CaseLaw and 83.6% on LegalBench, though it scores lower on ContractLaw (64.7%).
We just evaluated DeepSeek V3 on all benchmarks!
- DeepSeek V3 is DeepSeek’s latest model, boasting speeds of 60 tokens/second and claiming to be 3x faster than V2, with an average accuracy of 73.9% (4.2% better than previous versions).
- DeepSeek V3 performs comparably (slightly better) to Claude 3.7 Sonnet (71.7%).
- The model demonstrates strong legal capabilities, scoring particularly well on CaseLaw and LegalBench, though it scores lower on ContractLaw.
- It shows impressive academic versatility with top-tier performance on MGSM, Math500, and MedQA.
Today, we’re releasing results from the Multimodal Multi-task Benchmark (MMMU Pro), a comprehensive evaluation of AI models’ ability to reason across multiple modalities spanning 30 subjects in 6 major disciplines.
- o1 achieved the highest overall accuracy at 77.7%, surpassing the performance of the worst human experts (76.2%).
- Claude 3.7 Sonnet (Thinking) delivers performance nearly identical to o1 at a more favorable price point
- Even the best models remain well below the performance of the best human experts (88.6%), highlighting opportunities for further advancement
We just evaluated Command A on all benchmarks!
- Command A is Cohere’s most efficient and performant model to date, specializing in agentic AI, multilingual, and human evaluations for real-life use cases.
- On our proprietary benchmarks, Command A shows mixed performance, ranking 23rd out of 28 models on TaxEval but a good 10th out of 22 models on CorpFin.
- The model performs better on some academic benchmarks, scoring 78.7% on LegalBench (9th place) and 86.8% on MGSM (13th place).
- However, it struggles with AIME (13.3%, 12th place) and GPQA Diamond (29.3%, 18th place).
We just evaluated Jamba 1.6 Large and Jamba 1.6 Mini models!
- Jamba 1.6 Large and Jamba 1.6 Mini are the latest versions of the open source Jamba models, developed by AI21 Labs.
- On our private benchmarks, Jamba 1.6 Large shows reasonable performance, getting the 16th place out of 27 models on TaxEval. with 65.3% accuracy, beating GPT-4o Mini and Claude 3.5 Haiku.
- However both models are not competitive on public benchmarks, they get the last two places on AIME and GPQA Diamond.
Today, we’ve released five new academic benchmarks on our site: three evaluating mathematical reasoning, and two on general question-answering.
Unlike results released by model providers on these benchmarks, we applied a consistent methodology and prompt-template across models, ensuring an apples-to-apples comparison. You can find detailed information about our evaluation approach on each benchmark’s page:
We just released a new benchmark in partnership with Vontive!
- The MortgageTax benchmark evaluates language models on extracting information from tax certificates.
- It tests multimodal capabilities with 1258 document images, including both computer-written and handwritten content.
- The benchmark includes two key tasks: semantic extraction (identifying year, parcel number, county) and numerical extraction (calculating annualized amounts).
Claude 3.7 Sonnet leads the pack with 80.6% accuracy, and the other top 3 models are all from Anthropic.
We just released the VLAIR! Whereas our previous benchmarks study foundation model performance, here we investigate the ability of the most popular legal AI products to perform real world legal tasks.
To build a large, high quality dataset, we worked with some of the top global law firms, including Reed Smith, Fisher Phillips, McDermott Will & Emery, Ogletree Deakins, Paul Hastings among others. This is the first benchmark in which we also collected a human baseline against which we measure performance.
In sum, this enabled us to study how these legal AI systems perform on practical tasks and especially how the work of generative AI tools compared to that of a human lawyer.
Read the report for full results.
We just evaluated Anthropic’s Claude 3.7 Sonnet (Nonthinking) model!
- We evaluted the model with Thinking Disabled on all benchmarks. It shows great performance and reaches second place just behind its Thinking Enabled counterpart on Corp Fin.
- We also evaluated the model with Thinking Enabled. Unlike most models that excel in specific areas, Anthropic’s Claude 3.7 Sonnet (Thinking) demonstrates remarkable consistency, achieving top-tier performance across all evaluated benchmarks. The remaining two benchmarks are currently in progress due to their higher token requirements.
We have also run Google 2.0 Flash Thinking Exp and Google 2.0 Pro Exp on most benchmarks.
We just evaluated OpenAI’s o3-mini model!
- The model shows a good price-performance trade-off, reaching close to top places on our most recent and proprietary benchmarks like Tax Eval.
- However, o3-mini seems to struggle with large context windows, performing poorly on the Max Fitting Context task of CorpFin. It tends to lose the question if it is provided at the beginning of a large context window (around 150k tokens and more).
We have also run DeepSeek R1 on our CorpFin benchmark, on which it reaches the top place, beating all other models we have tested.
🐳 We just evaluated DeepSeek’s R1 model on three of our private datasets! 🐳
- The model demonstrates its strong reasoning ability, rivaling Open AI’s o1 model on our Tax dataset.
- However, R1 performs extremely poorly on ContractLaw and with middling performance on CaseLaw. The model’s performance is not uniform, suggest task-specific evaluation must be done before adoption
- Overall, this large Chinese model shows impressive ability and further closes the gap between closed and open-source models.
Vals AI and Graphite Digital partnered to release the first medical benchmark on Vals AI.
This report offers the first third-party, highly-exhaustive evaluation of over 15 of the most popular LLMs on graduate-level medical questions.
We assessed models under two conditions: unbiased and bias-injected questions, measuring the models’ general accuracy and the ability to handle racial bias in medical contexts.
Our top-performing model was OpenAI’s o1 Preview and best value was Meta’s Llama 3.1 70b.
Read the full report to find out more!
We just released two new benchmarks!
- We have released a completely new version of our CorpFin benchmark - with 1200 expert generated financial questions on very long context docs (200-300 pages).
- We have also released a completely new TaxEval benchmark, with more than 1500 expert reviewed tax questions.
We also are releasing several new models such as Grok 2 and Gemini 2.0 Flash Exp.
We’ve just implemented a re-design of this benchmarking website!
Apart from being easier on the eyes, this new version of the site is much more useful.
- Models cards are displayed on their own dedicated pages, showing results across all benchmarks.
- Every Benchmark page is time-stamped and updated with changelogs.
- Our Methodology page now shares more details around our approach and plan.
- On Legalbench, it’s now exactly tied with GPT 4o, and beats 4o on CorpFin and CaseLaw
- It usually, but not always, performs a few percentage points better than the previous version - for example, on Legalbench (+1.3%), ContractLaw Overall (+0.5%), and CorpFin (+0.8%).
- There are some instances where it experienced a performance regression - including TaxEval Free Response (-3.2%) and CaseLaw Overall (-0.1%).
- Although it’s competitive with 4o, it’s still not at the level of GPT o1, which still claims the top spots on almost all of our leaderboards.
Vals AI and Legaltech Hub are partnering with leading law firms and top legal AI vendors to conduct a first-of-its-kind benchmark.
The study will evaluate the platforms across eight legal tasks including Document Q&A, Legal Research, EDGAR Research. All data will be collected from the law firms, to ensure it’s representative of real legal work.
The report will be published in early 2025.
Introducing SAFE-Teen: evaluating AI chatbots on teen mental health
Hover or tap a dot to follow one configuration across all three areas.
Industry Leaderboard
Model performance on different sections of the economy.
Vibe Code Bench v1.1
Benchmark data not found
Model Performance Over Time
Tracking how foundation models improve with each release
•Oct 09, 2026